In-depth analysis of the next trillion-dollar track: the combination of zero-knowledge proof and distributed computing.
Original author: Xie Jinbin (X Research DAO)
Original editor: AndyHoo (X Research DAO)
1. Development History and Market Prospects of Distributed Computing
1.1 Development History
· Initially, each computer could only perform one computing task. With the emergence of multi-core and multi-threaded CPUs, a single computer can now execute multiple computing tasks.
· With the increase of business for large websites, it is difficult to scale up in single server mode and hardware costs are increased. Service-oriented architecture emerged, consisting of multiple servers. It consists of service registrars, service providers, and service consumers.
· However, with the increase of business and servers in the SOA model, the maintainability and scalability of point-to-point services become more difficult. Similar to the bus mode in microcomputer principles, the service bus appears to coordinate various service units. The service bus connects all systems together through a hub-like architecture. This component is called ESB (Enterprise Service Bus). As an intermediate role, it coordinates different formats or standards of service protocols.
· Subsequently, communication based on the REST model using application programming interfaces (APIs) stands out for its concise and highly composable features. Each service outputs interfaces to the outside world in REST form. When a client makes a request through a RESTful API, it passes on the representation of the resource state to the requester or terminal. This information or representation is transmitted in one of the following formats via HTTP: JSON (JavaScript Object Notation), HTML, XLT, Python, PHP, or plain text. JSON is the most commonly used programming language, although its name in English originally meant "JavaScript Object Notation", it is applicable to various languages and can be read by both humans and machines.
· Virtual machines, container technology, and three papers from Google:
In 2003, GFS: The Google File System was published.In 2004, MapReduce: Simplified Data Processing on Large Clusters was published.2006年,Bigtable: A Distributed Storage System for Structured DataThe opening of the distributed system era was marked by the emergence of distributed file systems, distributed computing, and distributed databases. Hadoop reproduced Google's paper, Spark is faster and easier to use, and Flink meets the needs of real-time computing.
· However, in the past, it has always been a distributed system, not a fully peer-to-peer system. In the Web3 field, it completely overturns the previous software architecture. Consistency in distributed systems, prevention of fraud attacks, prevention of dust trading attacks, and a series of other issues have brought challenges to decentralized computing frameworks.
· The smart contract public chain represented by Ethereum can be abstractly understood as a decentralized computing framework. However, the EVM is a virtual machine with a limited instruction set and cannot perform the general-purpose computing required by Web2. Moreover, on-chain resources are extremely expensive. Nevertheless, Ethereum has also broken through the bottleneck of peer-to-peer computing frameworks, such as peer-to-peer communication, network-wide consistency of computing results, and data consistency.
1.2 Market Outlook
Readers have learned about the history of distributed computing above, but there may still be many confusions. I will list some potential questions that readers may have, as follows:
· Starting from business needs, why is decentralized computing network important?
· What is the overall market size?
· What stage are we currently in and how much room is there for the future?
· What opportunities are worth paying attention to? How can we make money?
1.2.1 Why is decentralized computing important?
In the initial vision of Ethereum, it was meant to become the world's computer. In 2017, after the ICO boom, it was discovered that asset issuance was still the main focus. However, in 2020, the Defi summer emerged and a large number of Dapps began to emerge. On-chain data exploded, and in the face of increasingly complex business scenarios, the EVM became increasingly powerless. There is a need for off-chain expansion to achieve functions that the EVM cannot. Roles such as oracles are all to some extent decentralized computing.
We can further expand our thinking. Currently, Dapps are growing rapidly and the amount of data is also exploding. The value of this data requires more complex algorithms to calculate and mine its commercial value. The value of data is reflected and generated by computation. These are things that most smart contract platforms cannot achieve.
Nowadays, Dapp development is no longer just about completing the 0 to 1 process. It requires more powerful underlying infrastructure to support it in completing more complex business scenarios. The entire Web3 has moved beyond the stage of developing toy applications and will face more complex logic and business scenarios in the future.
1.2.2 What is the overall market size?
How to estimate the market size? Estimate it by the scale of distributed computing business in the Web2 field? Multiply it by the penetration rate of the Web3 market? Add up the valuations of corresponding financing projects currently available on the market?
We cannot simply apply the market scale of Web2's distributed computing to Web3, as the reason being:
1. Distributed computing in the Web2 era meets most needs, while decentralized computing in the Web3 era provides differentiated solutions to meet market demands. Simply copying the former would contradict the objective market environment.
2. The decentralized computing in the Web3 field will have a global market scope in the future. Therefore, we need to estimate the market size more rigorously.
Regarding the overall budget for potential Web3 industry tracks, the calculation is based on the following points:
1. Use the valuation of other projects that can be included in the industry as the benchmark market value. According to data from the coinmarketcap website, the market value of distributed computing projects in circulation on the market is $6.7 billion.
2. The revenue model comes from the design of the Token economic model. For example, the currently popular Token revenue model is that Token is used as a means of paying transaction fees during transactions. Therefore, the prosperity and transaction activity of the ecosystem can be indirectly reflected through the revenue from transaction fees, and ultimately used as a standard for valuation. Of course, Token also has other mature models, such as being used for mortgage mining, or as trading pairs for trading, or as anchor assets for algorithmic Stablecoins. Therefore, the valuation model of Web3 projects, unlike the traditional stock market, is more like a national currency. Tokens can have a variety of use cases, so specific projects require specific analysis. We can try to explore how to design the Token model in the decentralized computing scenario of Web3. First, let's assume that we are designing a decentralized computing framework. What challenges will we encounter?
a). Because a completely decentralized network requires resource providers to ensure online availability and service quality in such an untrusted environment, it is necessary to ensure that the incentive mechanism is reasonable and to prevent attackers from launching fraudulent attacks, witch attacks, and other attack methods in the game mechanism. Therefore, Token is needed as a pledge to participate in the POS consensus network to ensure the consensus consistency of all nodes. For resource contributors, their contribution workload needs to be incentivized through a certain incentive mechanism. Token incentives for business growth and network efficiency improvement must have a positive cycle of growth.
b). Compared to other layer1s, the network itself also generates a large number of transactions. Faced with a large number of dust transactions, each transaction pays a transaction fee, which is a token model verified by the market.
c). If the token is only used for practical purposes, it is difficult to further expand its market value. However, if it is used as an anchor asset for asset portfolio and undergoes multiple layers of asset nesting combination, it can greatly expand the financialization effect.
The overall valuation = collateralization rate * Gas consumption rate * (inverse of circulation) * individual price.
1.2.3 What stage is the industry currently in and how much potential does it have in the future?
From 2017 to now, many teams have been trying to develop in the direction of decentralized computing, but they have all failed. The reasons for the failures will be explained later. The exploration path started with projects similar to alien exploration plans, then developed into a model imitating traditional cloud computing, and finally explored the Web3 native model.
The current situation of the entire track is that it has achieved breakthroughs from 0 to 1 at the academic level, and some large-scale projects have made significant progress in engineering practice. For example, the current implementations of zkRollup and zkEVM are in the stage of just releasing products.
There is still a lot of room for growth in the future, for the following reasons:
2. More instruction sets need to be added and enriched.
3. Optimization of truly different business scenarios.
4. Business scenarios that were previously impossible to achieve with smart contracts can now be realized through decentralized computing.
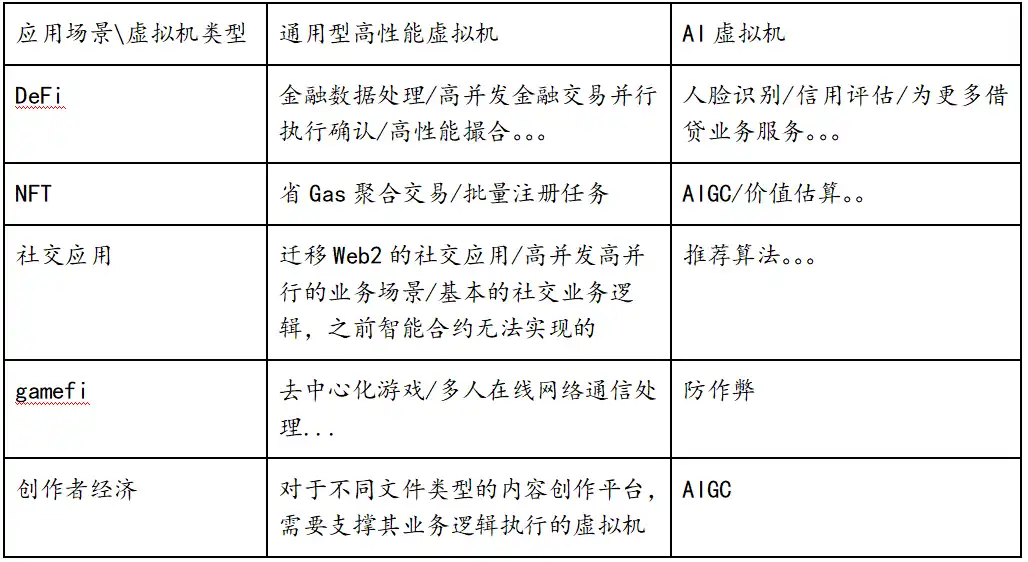
We will use a specific case to explain a completely decentralized game. Currently, most Gamefi requires a centralized service as the backend, which is responsible for managing player state data and some business logic. The frontend is responsible for user interaction logic and passing events to the backend. There is currently no complete solution on the market that can support Gamefi's business scenarios. However, a verifiable decentralized computing protocol has emerged, replacing the backend with zkvm. This can truly achieve decentralized games. The frontend sends user event logic to zkvm to execute relevant business logic, which is then verified and recorded in the decentralized database.
Of course, this is just one proposed use case, and there are many business scenarios in Web2 that require computational capabilities.
1.2.4 Which opportunities are worth paying attention to? How can we make money?
2. Decentralized Distributed Computing Experiment
2.1 Cloud Service Model
Currently, Ethereum has the following issues:
1. The overall throughput is low. Despite consuming a significant amount of computing power, the throughput is only equivalent to that of a single smartphone.
2. Low verification enthusiasm. This problem is called the Verifier's Dilemma. Nodes that obtain the right to package receive rewards, while other nodes need to verify without receiving rewards, resulting in low verification enthusiasm. Over time, this may lead to unverified calculations, posing a risk to the security of on-chain data.
3. Calculation is limited by gasLimit, and the cost of computation is relatively high.
A team has attempted to adopt the cloud computing model widely used by Web2. Users pay a certain fee based on the duration of their use of computing resources. This model is adopted because it is impossible to verify whether a computing task has been executed correctly, and can only be measured by detectable time parameters or other controllable parameters.
The final pattern was not widely used and did not consider human factors. A large amount of resources were used for mining in order to seek maximum benefits, resulting in fewer truly usable resources. This is the result of each role seeking to maximize their own interests within the game system.
The final result is completely opposite to the original intention.
2.2 Challenger Mode
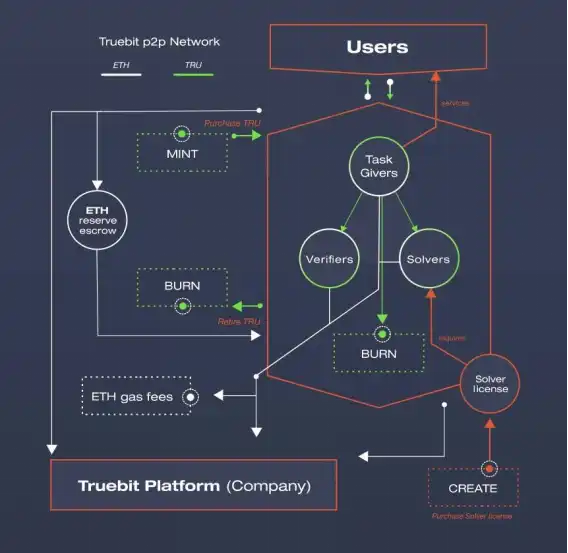
Meanwhile, TrueBit utilizes a game-theoretic system to achieve a globally optimal solution, ensuring that the issued computing tasks are executed correctly.
https://www.aicoin.com/article/256862.html
Our core points of this fast computing framework are:
1. Role: problem solver, challenger, and judge.
2. Problem solvers need to pledge funds in order to participate in receiving computational tasks.
3. As a challenger in the bounty hunting industry, you need to verify the calculation results of problem solvers and compare them with your own local results.
4. The challenger will extract the calculation task that is consistent with the calculation state of both parties at the nearest time. If there is a divergence, the Merkle tree hash value of the divergence point will be submitted.
5. Finally, the judge will determine whether the challenge is successful.
However, this mode has the following shortcomings:
1. Challengers can submit their work at a later time, as long as they complete the submission task. This results in a lack of timeliness.
2.3 Utilizing Zero-Knowledge Proofs to Verify Computations
So how to achieve both verifiability of the calculation process and timely verification.
For example, the implementation of zkEVM requires submitting verifiable zkProofs for each block time. This zkProof contains bytecode generated by the logical computation business code, which is then executed to generate circuit code. This ensures that the business logic is executed correctly and that verification is timely and guaranteed within a short and fixed time.
Although zkEVM is only for smart contract execution, it is essentially under the framework of computing business. If we extend the EVM logic to other general-purpose virtual machines, such as the WASM virtual machine, or the more general LLVM high-performance virtual machine. Of course, there will be many challenges in implementing this in engineering practice, but it gives us more room for exploration.
Under the assumption of sufficient high-performance zero-knowledge proof acceleration hardware and sufficiently optimized zero-knowledge proof algorithms, universal computing scenarios can be fully developed. A large number of computing businesses in Web2 scenarios can be replicated using zero-knowledge proof universal virtual machines. This is similar to the profitable business direction mentioned earlier.
3. Combination of Zero-Knowledge Proof and Distributed Computing
3.1 Academic Perspective
We look back at the historical development and evolution of zero-knowledge proof algorithms.
· GMR85 is the earliest algorithm, originating from the paper "The Knowledge Complexity of Interactive Proof Systems" (i.e. GMR85) published by Goldwasser, Micali, and Rackoff in 1989. This paper mainly explains how much knowledge needs to be exchanged after K rounds of interaction in an interactive system to prove that a statement is correct.
· Yao's Garbled Circuit (GC) [89]. A famous two-party secure computation protocol based on oblivious transfer, which can evaluate any function. The central idea of garbled circuits is to decompose the computation circuit (which can perform any arithmetic operation using AND, OR, and NOT circuits) into a generation phase and an evaluation phase. Each party is responsible for one phase, and the circuit is encrypted during each phase, so neither party can obtain information from the other, but they can still obtain results based on the circuit. Garbled circuits consist of an oblivious transfer protocol and a block cipher. The complexity of the circuit increases linearly with the size of the input. After the publication of garbled circuits, Goldreich-Micali-Wigderson (GMW) [91] extended the use of garbled circuits to multiple parties to resist malicious adversaries.
· The Sigma protocol, also known as the (special) zero-knowledge proof of honest verifier, assumes that the verifier is honest. This example is similar to the Schnorr identity authentication protocol, except that the latter usually uses non-interactive methods.
· In 2013, Pinocchio (PGHR13) was introduced as a protocol for Nearly Practical Verifiable Computation, which compresses proof and verification time to a practical range. This protocol serves as the foundation for Zcash.
· In 2016, Groth16: On the Size of Pairing-based Non-interactive Arguments simplified the proof size and improved verification efficiency, making it the most widely used ZK basic algorithm currently.
· In 2017, Bulletproofs (BBBPWM17) proposed the Bulletproof algorithm in their paper "Bulletproofs: Short Proofs for Confidential Transactions and More". This algorithm provides very short non-interactive zero-knowledge proofs that do not require trusted setup. Six months later, it was applied to Monero and proved to be a fast combination of theory and application.
· In 2018, zk-STARKs (BBHR18) Scalable, transparent, and post-quantum secure computational integrity was proposed, which is a ZK-STARK algorithm protocol that does not require a trusted setup. This is also another remarkable direction in the development of ZK, and it is the basis for the creation of StarkWare, the most heavyweight ZK project.
Bulletproofs are characterized by:
1) Short NIZK without trusted setup
2) Construct based on Pedersen commitment
3) Support proof aggregation.
4) Prover time is: O(N log(N)), approximately 30 seconds.
5) Verifier time is: O(N), approximately 1 second.
6) The proof size is: O(log(N)), approximately 1.3KB.
7) The security assumption is based on: discrete log.
The scenarios applicable to Bulletproofs are:
1) range proofs (only about 600 bytes needed)
2)inner product proofs
3) Intermediary checks in the MPC protocol.
4)aggregated and distributed (with many private inputs) proofs
Halo2's main features are:
1) Efficiently combine accumulation scheme with PLONKish arithmetization without the need for trusted setup.
2) Based on the IPA commitment scheme.
3) Flourishing developer ecosystem.
4) Prover time is: O(N*logN).
5) Verifier time is: O(1) > O(1) > O(1) > Groth16.
6) Proof size is: O(log N).
7) The security assumption is based on discrete log.
The scenarios applicable to Halo2 are:
1) Arbitrary Verifiable Computation
2) Recursive proof composition
3) Circuit-optimized hashing based on lookup-based Sinsemilla function.
Halo2 is not suitable for the following scenarios:
1) The verification cost is high on Ethereum unless KZG version of Halo2 is used for replacement.
Plonky2's main features are:
1) Combine FRI with PLONK without the need for a trusted setup.
2) Optimizations have been made for processors with SIMD and 64 byte Goldilocks fields have been adopted.
3) Prover time is: O(log N).
4) Verifier time is: O(log N).
5) Proof size is: O(N*logN).
6) The security assumption it is based on is: collision-resistant hash function.
Plonky2 is suitable for the following scenarios:
1) Verifiable computation.
2) Recursive proof composition.
3) Use custom gates for circuit optimization.
Plonky2 is not suitable for the following scenarios:
1) Limited by its non-native arithmetic, it is not suitable for statements that involve elliptic curve operations.
Currently, Halo2 has become the mainstream algorithm used by zkvm, supporting recursive proof and verification of any type of computation. It lays the foundation for universal computation scenarios for zero-knowledge proof type virtual machines.
3.2 Engineering Practice Level
Since zero-knowledge proofs have made great progress in the academic field, what is the current progress when it comes to practical development?
We observe from multiple perspectives:
· Programming languages: Currently, there are specialized programming languages that help developers without the need to deeply understand how circuit code is designed, thus reducing the development threshold. Of course, there are also those that support translating Solidity into circuit code. The friendliness level for developers is increasing.
· Virtual Machine: Currently, there are multiple implementations of zkvm. The first is a self-designed programming language that compiles into circuit code through its own compiler, and finally generates zkproof. The second is to support the solidity programming language, which compiles into target bytecode through LLVM, and finally translates into circuit code and zkproof. The third is a true EVM equivalent compatibility, which translates the execution operations of bytecode into circuit code and zkproof. Is this the final battle of zkvm? Not yet. Whether it is expanding to general computing scenarios beyond smart contract programming, or complementing and optimizing the underlying instruction set of different zkvm solutions, it is still in the 1 to N stage. There is still a lot of work to be done in optimizing and implementing engineering. Each company has implemented it from the academic level to the engineering level. Who can ultimately become the king and break through? Not only does it need to make significant progress in performance improvement, but it also needs to attract a large number of developers to enter the ecosystem. The timing is a very important prerequisite factor. Pushing to the market first, attracting fund precipitation, and the applications that emerge spontaneously within the ecosystem are all key factors for success.
· Peripheral supporting tools and facilities: editor plugin support, unit testing plugin, Debug debugging tool, etc., to help developers develop zero-knowledge proof applications more efficiently.
· Infrastructure for accelerating zero-knowledge proof: Because FFT and MSM take up a lot of computation time in the entire zero-knowledge proof algorithm, parallel computing devices such as GPU/FPGA can be used to execute them in parallel, achieving the effect of compressing time costs.
· Implementation in different programming languages: for example, using more efficient or better performing programming languages such as Rust.
· Emerging star projects: zkSync, Starkware, and other high-quality projects have successively announced the time of their official product releases. This indicates that the combination of zero-knowledge proofs and decentralized computing is no longer just a theoretical concept, but is gradually maturing in engineering practice.
4. Bottlenecks Encountered and How to Solve Them
4.1 zkProof generation efficiency is low
Previously, we talked about the market capacity, current industry development situation, and actual technological progress. However, are there no challenges present?
We break down the entire process of generating zkProof:
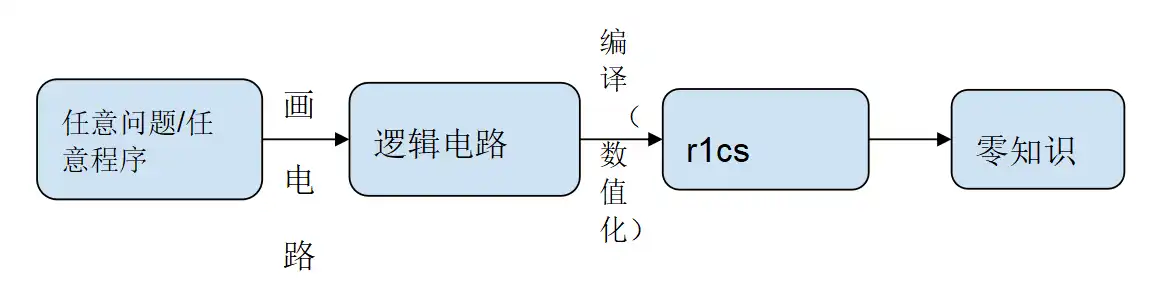
During the compilation of numerical R1CS in logical circuit, 80% of the computational workload is on NTT and MSM calculations. In addition, hash algorithms are applied to different levels of logical circuits, and the time cost of hash algorithms increases linearly with the number of levels. However, the industry has proposed the GKR algorithm, which reduces the time cost by 200 times.
However, the calculation time cost of NTT and MSM is still high. If you want to reduce the waiting time for users and improve the user experience, you must accelerate it in terms of mathematical implementation, software architecture optimization, GPU/FPGA/ASIC, and other aspects.
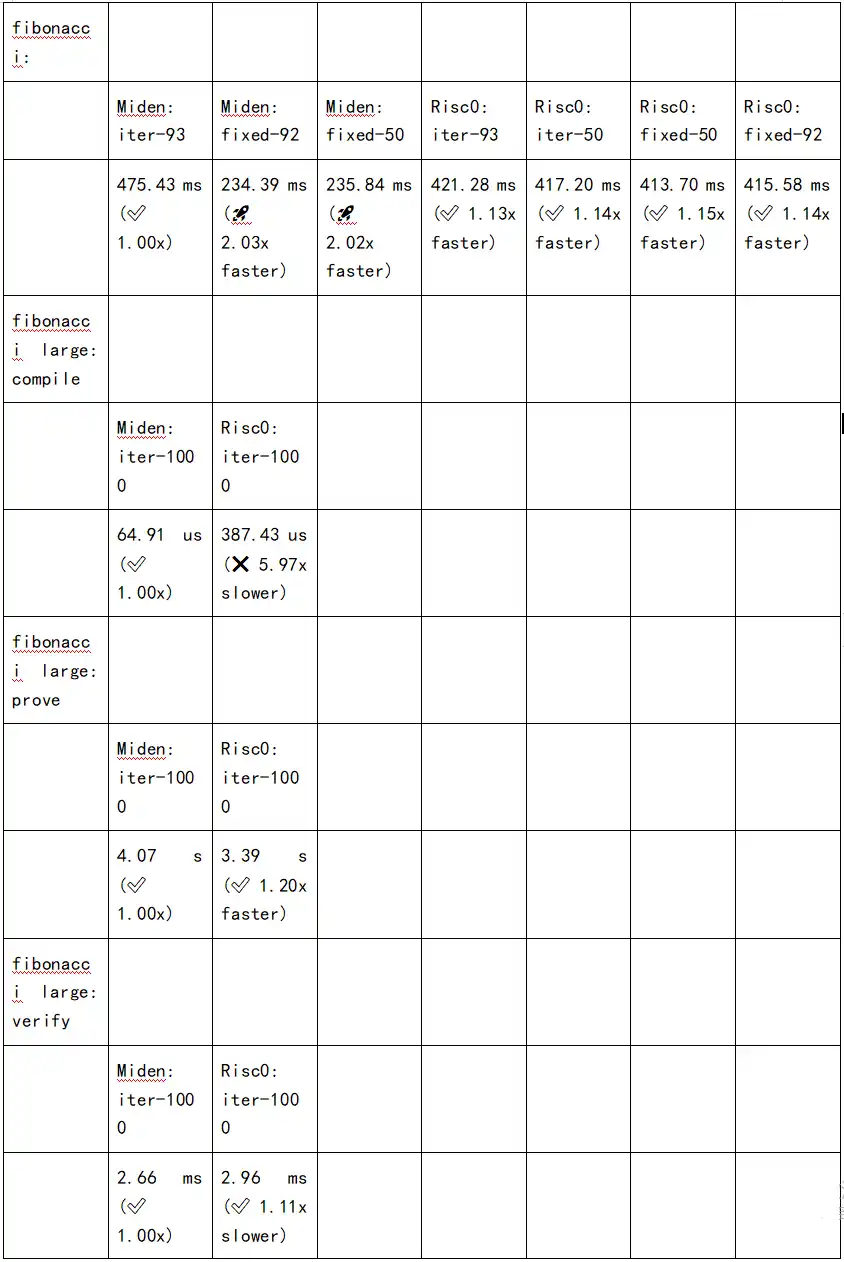
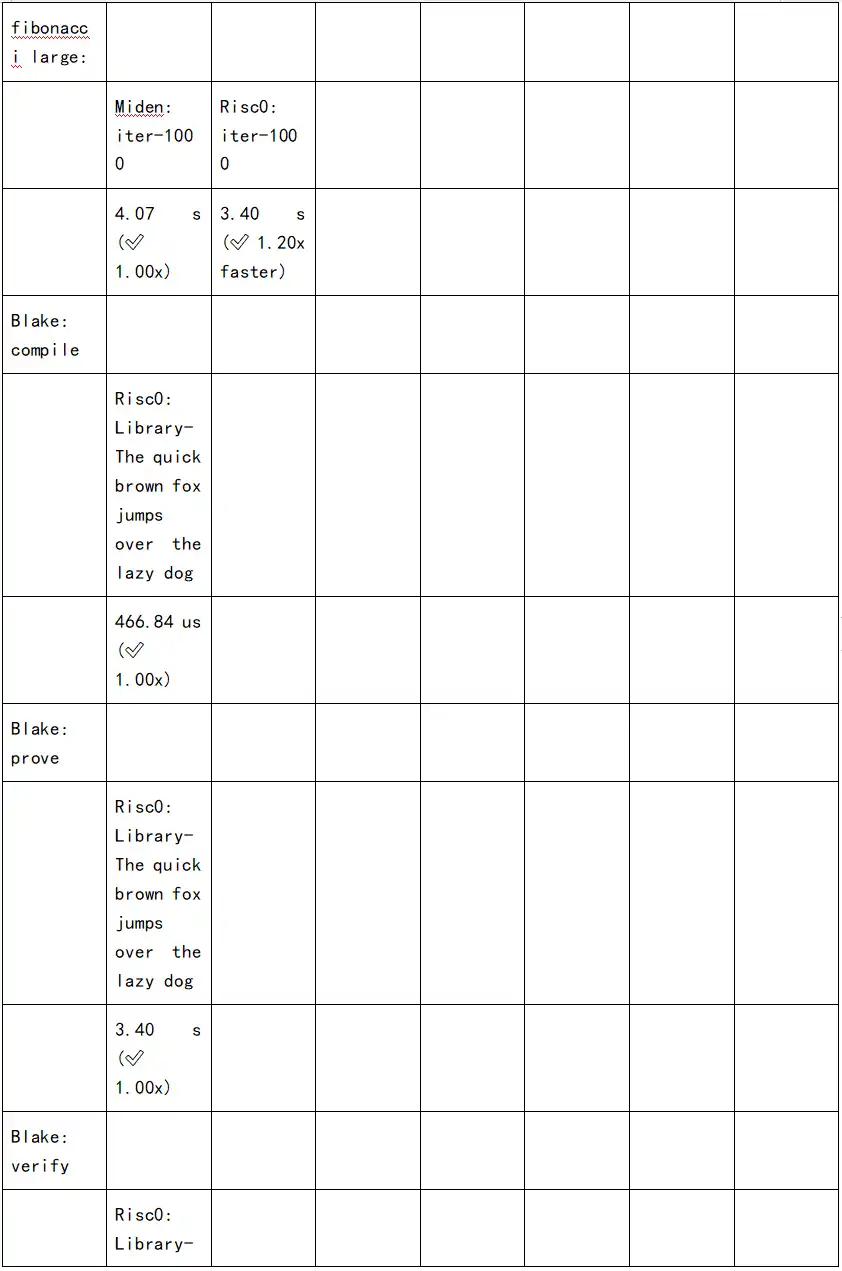
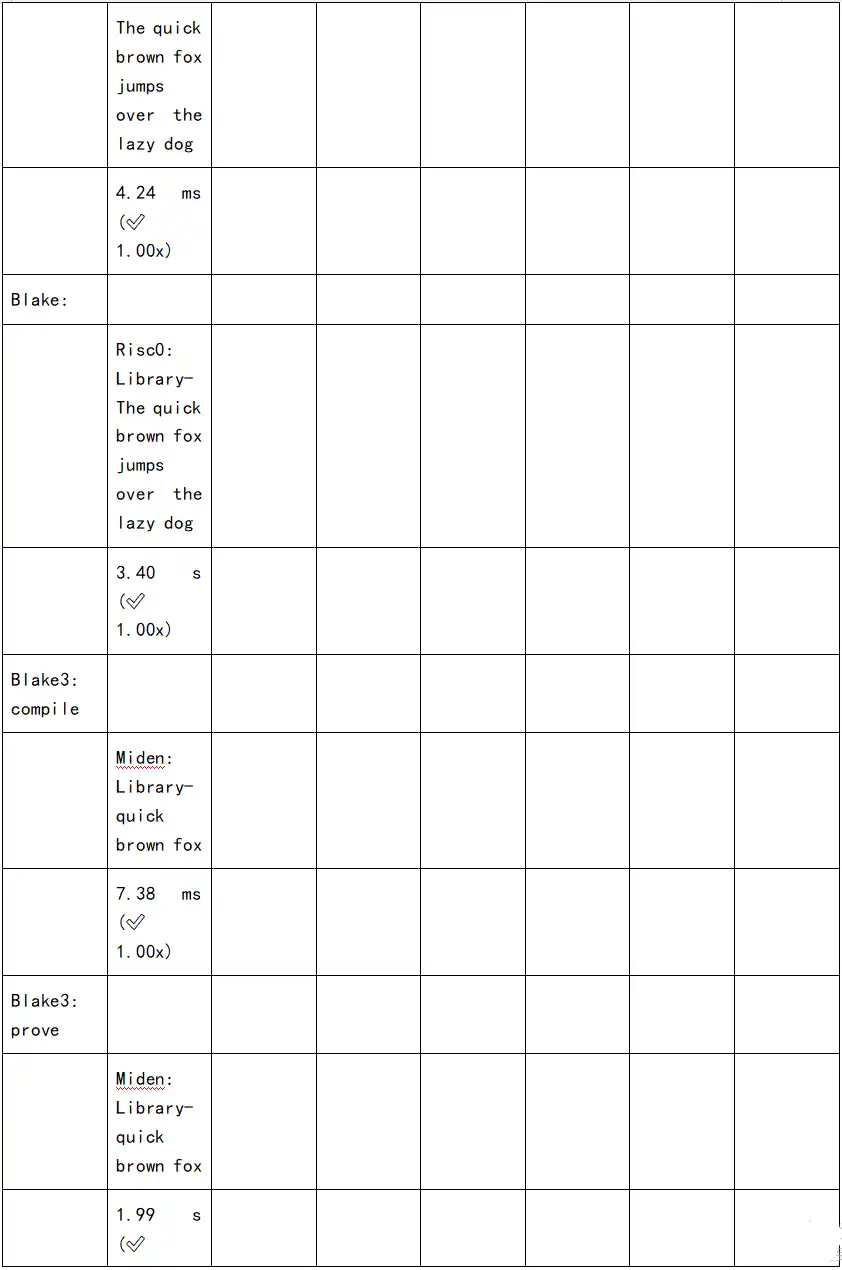
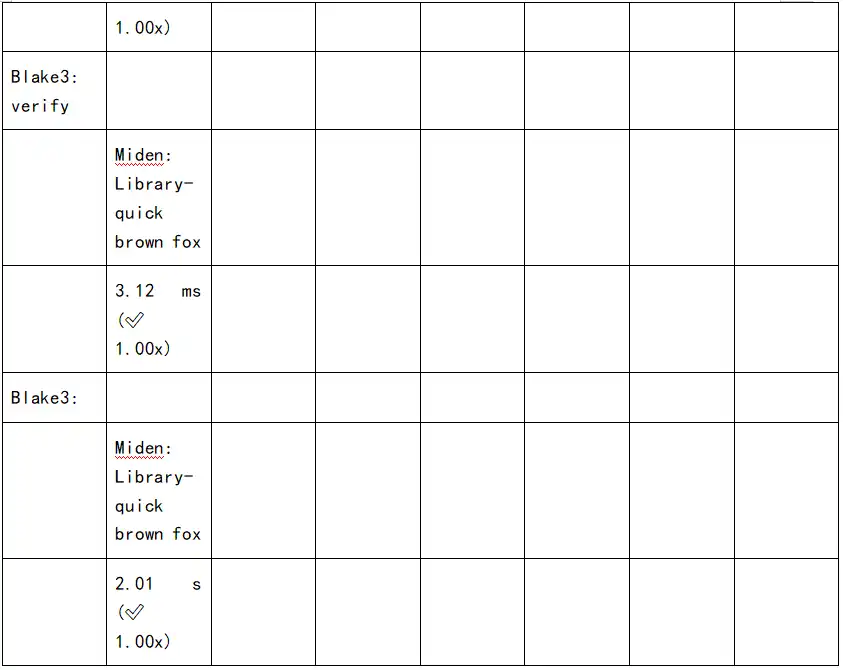
The following figure shows the test results of proof generation time and verification time for various zkSnark family algorithms:
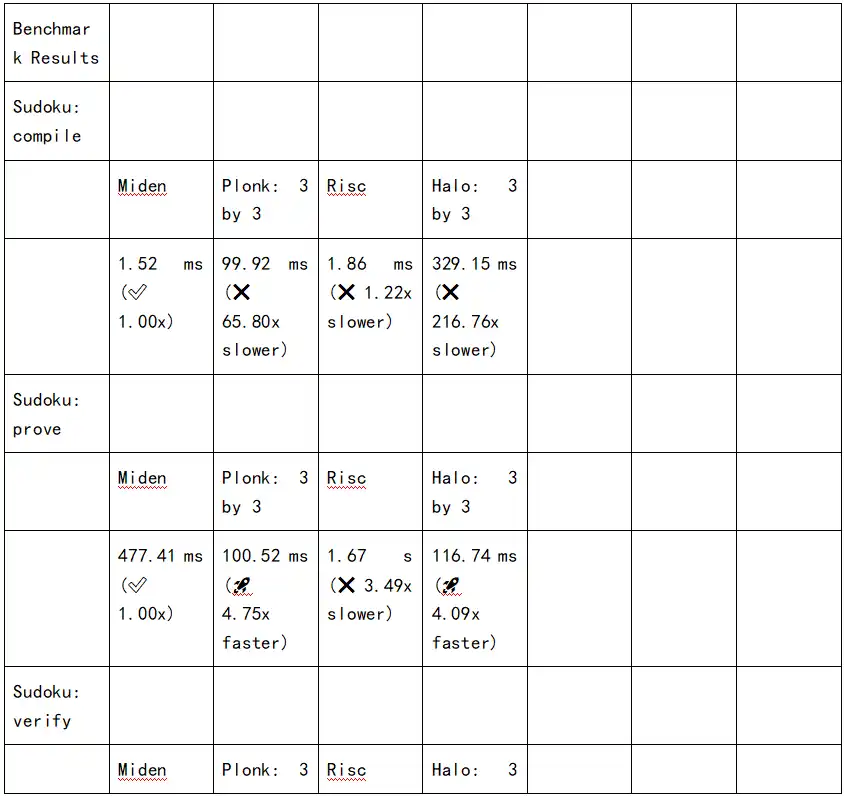
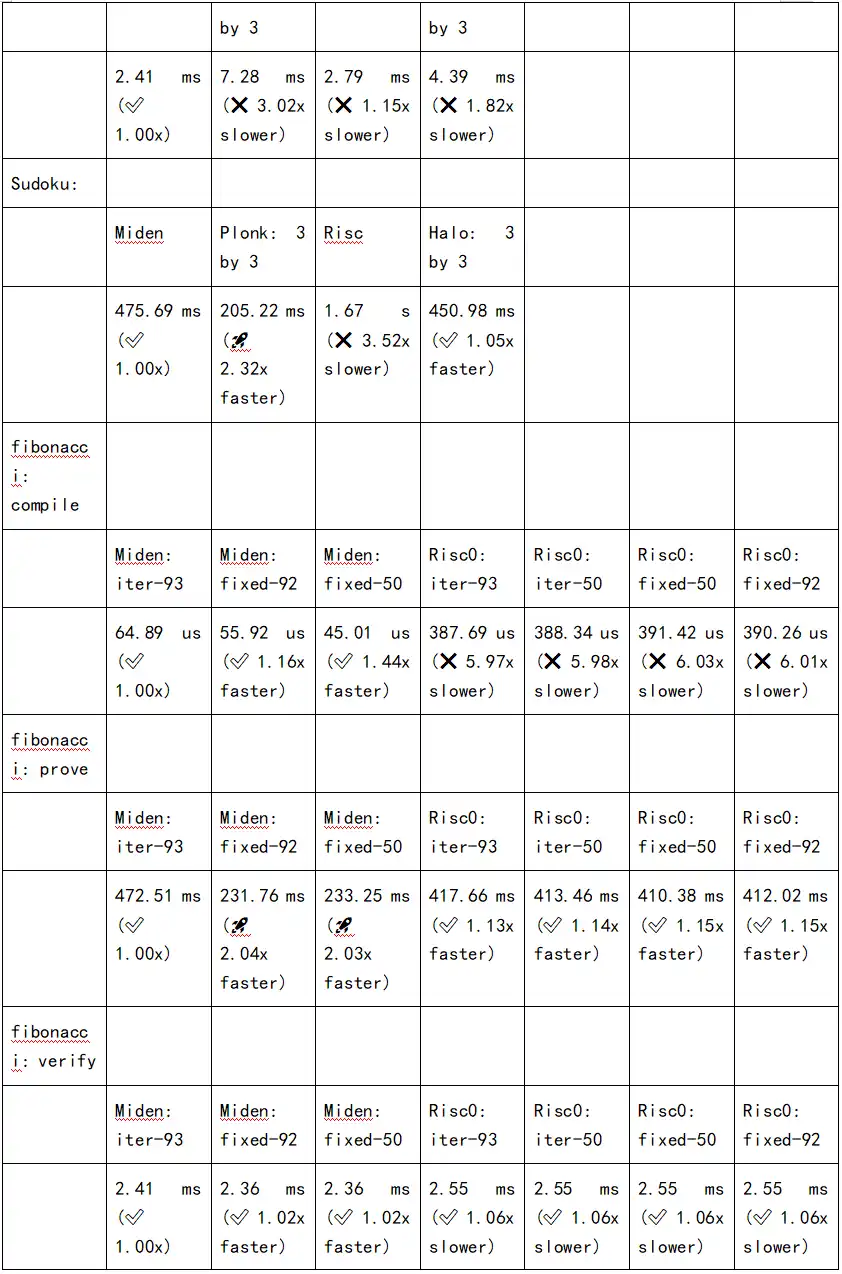
Since we can see the defects and challenges, it also means that there are opportunities hidden within:
1. Design chips for accelerating specific zkSnark algorithms or general zkSnark algorithms. Compared to other types of encryption algorithms, zkSnark generates more temporary files, which requires memory and graphics memory for devices. Chip start-up projects also face a large amount of capital investment, and there is no guarantee that they will be able to successfully produce chips in the end. However, once successful, their technological barriers and IP protection will be a moat. Chip project start-ups must have sufficient bargaining power channels to obtain the lowest cost and ensure overall quality control.
2. Graphics card acceleration Saas service, which utilizes graphics cards for acceleration, has lower costs than ASIC design and shorter development cycles. However, in terms of software innovation, it will eventually be replaced by hardware acceleration in the long run.
4.2 High Hardware Resource Consumption
Currently, after being in contact with some zkRollup projects, it was found that large memory and graphics cards with large video memory are more suitable for software acceleration. For example, in Filecoin mining, a large number of idle data packaging machines have become the target devices for popular zkRollup projects. In Filecoin mining, during the C2 phase, the generated circuit code files need to be generated and cached in memory.
If the business code logic is very complex, the corresponding generated circuit code will also be very large, and the final presentation form is a large temporary file. Especially when it comes to Hash calculation of circuit code, AMD CPU instructions are needed to accelerate. Because of the high-speed exchange between CPU and memory, the efficiency is very high. NVME solid-state hard drives are also needed to accelerate zkSnark operations. Above, we have discussed the possibility of implementing acceleration and found that the resource requirements are still very high.
In the future, if we want to popularize zkSnark applications on a large scale, it is imperative to optimize them at different levels.
4.3 Gas Consumption Cost
We observe that all zkRollup Layer2 solutions need to pass zkProofs to Layer1 for verification and storage, because resources on the ETH chain are very expensive. If widely adopted, this would require paying a large amount of Gas for ETH. Ultimately, this cost would be borne by users, which goes against the original intention of technological development.
So many zkp projects propose the use of data availability layers, zkProofs that utilize recursive proof composition, and compressed submissions, all in an effort to reduce Gas cost.
4.4 Instruction Missing in Virtual Machine
Currently, most zkvm-based platforms for smart contract programming require a significant amount of work to supplement the underlying instruction set of zkvm for more general computing scenarios. For example, the zkvm virtual machine supports libc instructions and matrix operation instructions, as well as other more complex computing instructions.
5. Conclusion
As smart contract platforms are more oriented towards asset programming, the combination of zero-knowledge proofs and decentralized computing presents an opportunity for more real-world business scenarios to be integrated into Web3. Accordingly, zero-knowledge proofs are expected to become a mainstream track rather than a technology confined to niche areas.
About Huobi Research Institute
Huobi Blockchain Application Research Institute (referred to as "Huobi Research Institute") was established in April 2016. Since March 2018, it has been committed to comprehensively expanding the research and exploration of various fields of blockchain. As the research object, the research goal is to accelerate the research and development of blockchain technology, promote the application of the blockchain industry, and promote the ecological optimization of the blockchain industry. The main research content includes industry trends, technology paths, application innovations in the blockchain field, Model exploration, etc. Based on the principles of public welfare, rigor and innovation, Huobi Research Institute will carry out extensive and in-depth cooperation with governments, enterprises, universities and other institutions through various forms to build a research platform covering the complete industrial chain of the blockchain. Industry professionals provide a solid theoretical basis and trend judgments to promote the healthy and sustainable development of the entire blockchain industry.
About X Research DAO
X Research DAO is a community-based research DAO backed by Huobi Research. It aims at being one of the most valuable decentralized blockchain-analysis insitituions in the world. X research DAO focuses on analysing web3 projects, early stage public-chains, gamefis and NFTs.
X Research DAO welcomes all web3 enthusiasts, let's build the best research DAO and learn together!
Disclaimer
1. The author of this report and his organization do not have any relationship that affects the objectivity, independence, and fairness of the report with other third parties involved in this report.
2. The information and data cited in this report are from compliance channels. The sources of the information and data are considered reliable by the author, and necessary verifications have been made for their authenticity, accuracy and completeness, but the author makes no guarantee for their authenticity, accuracy or completeness.
3. The content of the report is for reference only, and the facts and opinions in the report do not constitute business, investment and other related recommendations. The author does not assume any responsibility for the losses caused by the use of the contents of this report, unless clearly stipulated by laws and regulations. Readers should not only make business and investment decisions based on this report, nor should they lose their ability to make independent judgments based on this report.
4. The information, opinions and inferences contained in this report only reflect the judgments of the researchers on the date of finalizing this report. In the future, based on industry changes and data and information updates, there is the possibility of updates of opinions and judgments.
5. The copyright of this report is only owned by X Research DAO. If you need to quote the content of this report, please indicate the source. If you need a large amount of references, please inform in advance (see "About X Research DAO" for contact information) and use it within the allowed scope. Under no circumstances shall this report be quoted, deleted or modified contrary to the original intent.
This article is from a submission and does not represent the views of BlockBeats.
Welcome to join the official BlockBeats community:
Telegram Subscription Group: https://t.me/theblockbeats
Telegram Discussion Group: https://t.me/BlockBeats_App
Official Twitter Account: https://twitter.com/BlockBeatsAsia

 Related Articles