How does Vitalik Buterin interpret EIP-4844, which has a critical impact on Layer2?
Original title: 《 Proto-Danksharding FAQ 》
Original author: Vitalik Buterin
Original translation: Kyle, Babbitt
Ethereum founder Vitalik Buterin recently answered questions related to Proto-danksharding (also known as EIP-4844). Danksharding is a new sharding design proposed for Ethereum. What exactly can this technology bring?
What is Danksharding?
Danksharding is a new sharding design proposed for Ethereum, which introduces some significant simplifications compared to previous designs.
The main difference between all recent Ethereum sharding proposals since 2020 (including Danksharding and the previous one) and most non-Ethereum sharding proposals is Ethereum's Rollup-centric roadmap: Ethereum shards do not provide more space for transactions, but for data, which the Ethereum protocol itself does not try to interpret. Verifying a blob only requires checking whether the blob is available, i.e., whether it can be downloaded from the network. The data space in these blobs is expected to be used by the Layer 2 Rollup protocol that supports high-throughput transactions.
The main innovation introduced by Danksharding is the merged fee market: instead of a fixed number of shards, each with different blocks and different block proposers, in Danksharding there is only one proposer that selects all transactions and all data that go into that slot.
To avoid this design putting high system requirements on validators, we introduced Proposer/Builder Separation (PBS): a special class of participants called block builders bid for the right to select a slot, and proposers only need to select the valid header with the highest bid. Only block builders need to process the entire block (here, too, third-party decentralized oracle protocols can be used to implement distributed block builders); all other validators and users can validate blocks very efficiently via data availability sampling (remember: a "large" part of a block is just data).
What is proto-danksharding (aka EIP-4844)?
Proto-danksharding (aka EIP-4844) is an Ethereum Improvement Proposal (EIP) that implements much of the logic and "scaffolding" that makes up the full Danksharding specification (e.g. transaction format, validation rules), but has not yet actually implemented any sharding. In the proto-danksharding implementation, all validators and users must still verify the availability of the full data directly.
The main feature introduced by proto-danksharding is a new transaction type, which we call a transaction with a blob. A transaction with a blob is similar to a regular transaction, except that it also carries additional data called a blob. Blobs are very large (~125 kB) and are much cheaper than a similar amount of calldata. However, EVM execution cannot access the blob data; the EVM can only view commitments to the blob.
Because validators and clients still need to download the full blob contents, the data bandwidth target in proto-danksharding is 1 MB per slot, rather than the full 16 MB. However, since this data does not compete with the gas usage of existing Ethereum transactions, there is still a big scalability benefit.
Why is it okay to add 1MB of data to a block that everyone has to download, but not to make calldata 10x cheaper?
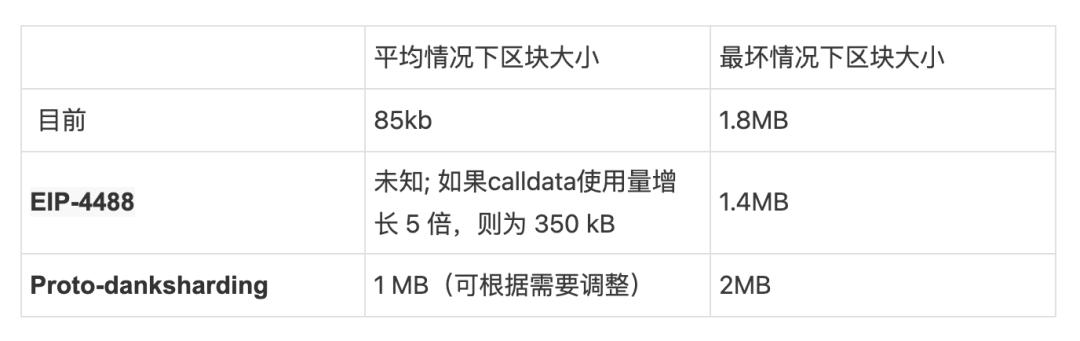
This has to do with the difference between average and worst-case load. Today, we already have an average block size of about 90 kB, but the maximum theoretically possible block size (if all 30M gas in a block is used for calldata) is about 1.8 MB. The Ethereum network has processed blocks close to that maximum in the past. However, if we simply reduced the calldata gas cost by a factor of 10, then while the average block size would increase to a still acceptable level, the worst case would become 18 MB, which is simply too much for the Ethereum network to handle.
The current gas pricing scheme fails to separate these two factors: the ratio between average and worst-case load depends on user choices about how much gas to spend on calldata vs. other resources, which means that gas prices must be set based on worst-case likelihood, causing average loads to be unnecessarily lower than what the system can handle. However, if we change gas pricing to more explicitly create a multi-dimensional fee market, we can avoid the average/worst-case load mismatch and include in each block close to the maximum amount of data we can safely process. Proto-danksharding and EIP-4488 are two proposals to do this.
How does proto-danksharding compare to EIP-4488?
EIP-4488 is an earlier and simpler attempt to solve the same average-case/worst-case load mismatch problem. EIP-4488 does this using two simple rules:
Calldata gas cost reduced from 16 gas per byte to 3 gas per byte
1 MB limit per block plus an extra 300 bytes per transaction (theoretical maximum: ~1.4 MB)
The hard limit is the simplest way to ensure that a large increase in average-case load does not result in an increase in worst-case load. The reduction in gas costs will greatly increase the use of rollups, potentially increasing the average block size to hundreds of KB, but the hard limit will directly prevent the worst-case possibility of a single block containing 10 MB. In fact, the worst-case block size would be smaller than it is today (1.4 MB vs. 1.8 MB).
Proto-danksharding instead creates a separate transaction type that holds cheaper data in large fixed-size blobs, and limits how many blobs can be included in each block. These blobs are not accessible from the EVM (only commitments to the blobs), and the blobs are stored by the consensus layer (the beacon chain) rather than the execution layer.
The main practical difference between EIP-4488 and proto-danksharding is that EIP-4488 tries to minimize the changes required today, while proto-danksharding makes a lot of changes today so that upgrading to full sharding in the future requires very few changes. While implementing full sharding (with data availability sampling, etc.) is a complex task, and will remain a complex task after proto-danksharding, that complexity is contained in the consensus layer. Once proto-danksharding is launched, no further work is required by execution layer client teams, rollup developers, and users to complete the transition to full sharding.
Note that the choice between the two is not an either-or: we can implement EIP-4488 as soon as possible, and then follow it up with proto-danksharding half a year later.
What parts of full danksharding does proto-danksharding implement, and what else needs to be implemented?
Quote EIP-4844:
Work already done in this EIP includes: · A new transaction type with the exact same format that needs to exist for "full sharding". · All execution layer logic required for full sharding. · All execution/consensus cross-validation logic required for full sharding. · Layer separation between BeaconBlock validation and data availability sampling blobs. · Most of the BeaconBlock logic required for full sharding. · Self-adjusting independent gasprice for blobs. Work still to be done to achieve full sharding includes: · Low-level extension of blob_kzgs in the consensus layer to allow 2D sampling. · Actual implementation of data availability sampling, · PBS (proposer/builder separation) to avoid requiring a single validator to process 32MB of data in a slot. · Proof of custody or similar in-protocol requirement for each validator to validate a specific portion of the shard data in each block.
Note that all of the remaining work is consensus layer changes and does not require any additional work by client teams, users, or Rollup developers.
What about the increased disk space requirements associated with all of these very large blocks?
Both EIP-4488 and proto-danksharding result in a long-term maximum usage of about 1 MB per slot (12 seconds). This equates to about 2.5 TB per year, which is much higher than the growth rate Ethereum requires today.
In the case of EIP-4488, addressing this requires a history expiration scheme (EIP-4444), where clients are no longer required to store history beyond a certain period of time (durations from 1 month to 1 year have been proposed).
In the case of proto-danksharding, the consensus layer can implement separate logic to automatically delete blob data after a period of time (e.g. 30 days), regardless of whether EIP-4444 is implemented. However, regardless of the short-term data scaling solution adopted, it is highly recommended to implement EIP-4444 as soon as possible.
Both strategies limit the additional disk load on consensus clients to a few hundred GB at most. In the long run, adopting some history expiration mechanism is essentially mandatory: a full shard will increase by about 40 TB of historical blob data per year, so users can only realistically store a small portion of this for a period of time. Therefore, it is worth setting expectations about this early.
If the data is deleted after 30 days, how will users access old blobs?
The purpose of the Ethereum consensus protocol is not to guarantee permanent storage of all historical data. Instead, the purpose is to provide a highly secure real-time bulletin board and leave room for other decentralized protocols to do longer-term storage. The bulletin board exists to ensure that data posted on the bulletin board is available long enough so that any user who wants that data, or any long-term protocol that backs up the data, has enough time to get the data and import it into their other applications or protocols.
In general, long-term historical storage is easy. While 2.5 TB per year is too big a requirement for regular nodes, it is very manageable for dedicated users: you can buy very large hard drives for about $20 per TB, which is perfectly adequate for hobbyists. Unlike consensus, which has an N/2-of-N trust model, historical storage has a 1-of-N trust model: you only need one of the data storers to be honest. Therefore, each piece of historical data only needs to be stored hundreds of times, rather than the full thousands of nodes that are doing real-time consensus verification.
Some practical ways to store the full history and make it easily accessible include:
Application-specific protocols (e.g. Rollup) may require their nodes to store the parts of the history that are relevant to their application. Lost historical data poses no risk to the protocol, only to the individual application, so it makes sense for the application to bear the burden of storing data relevant to itself.
Storing historical data in BitTorrent, for example. A 7 GB file containing blob data from blocks is automatically generated and distributed every day.
The Ethereum portal network (currently under development) could be easily extended to store history.
Block explorers, API providers, and other data services might store the full history.
Individual hobbyists and academics doing data analysis might store the full history. In the latter case, storing the history locally provides them with significant value because it makes it easier to compute directly on it.
Third-party indexing protocols such as TheGraph could potentially store the full history.
At higher levels of history storage (e.g. 500 TB per year), the risk of some data being forgotten becomes higher (plus, data availability verification systems become more strained). This may be the true limit of sharded blockchain scalability. However, all currently proposed parameters are very far from this point.
What is the format of blob data and how is it committed?
A blob is a vector of 4096 field elements, numbers in the range:
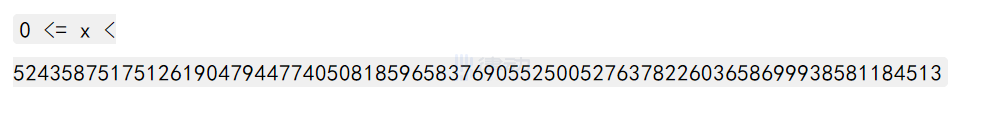
A blob is mathematically viewed as representing a polynomial of degree <4096 over a finite field with the above modulus, where the field element at position i in the blob is the evaluation of that polynomial at wi. w is a constant such that w=1.
The commitment to a blob is the KZG commitment to a hash of that polynomial. However, from an implementation point of view, it is not important to focus on the mathematical details of the polynomial. Instead, there will only be a vector of elliptic curve points (based on the Lagrangian trusted setup), and the KZG commitment to the blob will be just a linear combination. Quoting the code from EIP-4844:
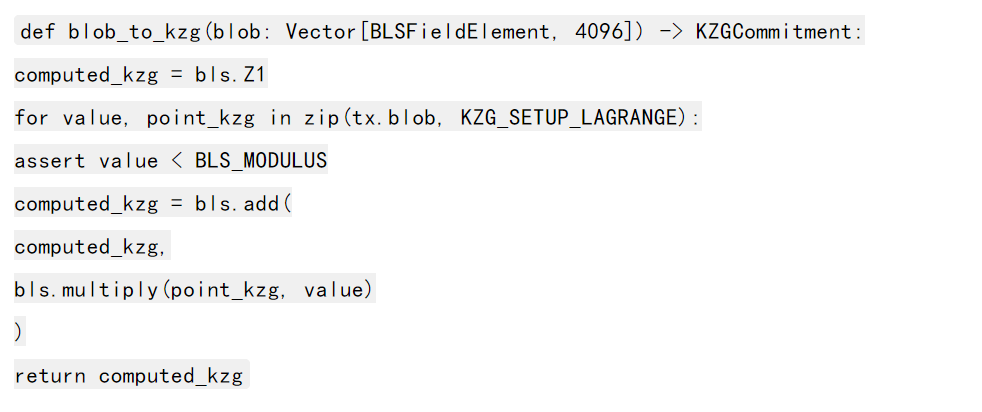
BLS_MODULUS is the modulus mentioned above, and KZG_SETUP_LAGRANGE is a vector of elliptic curve points, which is a Lagrangian-based trusted setup. It is reasonable for implementers to simply treat this as a black-box dedicated hash function for now.
Why use KZG's hash instead of using KZG directly?
Instead of using KZG to represent blobs directly, EIP-4844 uses a versioned hash: a single 0x01 byte (indicating the version) followed by the last 31 bytes of the SHA256 hash of KZG.
This is done for EVM compatibility and future compatibility: KZG commitments are 48 bytes, while the EVM more naturally uses 32-byte values, and if we switch from KZG to something else (e.g., for quantum resistance reasons), KZG commitments can continue to be 32 bytes.
What are the two precompiles introduced in proto-danksharding?
Proto-danksharding introduces two kinds of precompiles: the blob validation precompile and the point evaluation precompile.
The blob validation precompile is self-explanatory: it takes a versioned hash and a blob as input, and verifies that the provided versioned hash is actually a valid versioned hash of the blob. This precompile is intended to be used by Optimistic Rollup. Quoting EIP-4844:
Optimistic Rollup only requires that the underlying data is actually provided when submitting a fraud proof. The fraud proof submission function will require the entire contents of the fraud blob to be submitted as part of the calldata. It will use the blob verification function to verify the data against the previously submitted versioned hash, and then perform fraud proof verification on that data as it does today.
The point-evaluation precompile takes as input a versioned hash, an x-coordinate, a y-coordinate, and a proof (a KZG commitment to the blob and a proof of the KZG evaluation). It verifies the proof to check that P(x) = y, where P is the polynomial represented by the blob with the given versioned hash. This precompile is intended to be used by ZK Rollup. Quoting EIP-4844:
A ZK rollup will provide two commitments to its transaction or state delta data: the KZG in the blob, and some commitment using whatever proof system ZK rollup uses internally. They will use the equivalent protocol's commitment proof, using the point-evaluation precompile, to prove that the kzg (which the protocol ensures points to available data) and the ZK rollup's own commitment refer to the same data.
Note that most major Optimistic Rollup designs use a multi-round fraud-proof scheme where the final round requires only a small amount of data. Therefore, it is conceivable that Optimistic Rollup could also use point evaluation precompiles instead of blob verification precompiles, and it would be cheaper to do so.
What does the KZG trusted setup look like?
See:
https://vitalik.ca/general/2022/03/14/trustedsetup.html
A general description of how the powers-of-tau trusted setup works
https://github.com/ethereum/research/blob/master/trusted_setup/trusted_setup.py
An example implementation of all important trusted setup related calculations
In particular, in our case, the current plan is to run four ceremonies (with different secrets) of sizes (n1=4096,n2=16), (n1=8192,n2=16), (n1=16834,n2=16) and (n1=32768,n2=16) in parallel. In theory, only the first one is needed, but running more with larger sizes improves applicability in the future by allowing us to increase the blob size. We can't just have a larger set, because we want to be able to have a hard limit on the number of polynomials that can be submitted efficiently, and this limit is equal to the blob size.
A possible practical approach would be to start with a Filecoin setup, then run a ceremony to extend it. Multiple implementations, including browser implementations, would allow many people to participate.
Can't we use some other commitment scheme without a trusted setup?
Unfortunately, using anything other than KZG (e.g. IPA or SHA256) makes the sharding roadmap much more difficult. There are several reasons for this:
Non-arithmetic commitments (e.g. hash functions) are incompatible with data availability sampling, so if we use such a scheme, we'll have to change to KZG anyway when we move to full sharding.
IPA might be compatible with data availability sampling, but it leads to more complex schemes with weaker properties (e.g. self-healing and distributed block construction become more difficult)
Neither hashing nor IPA are compatible with cheap implementations of point evaluation precompiles. Therefore, hash- or IPA-based implementations will not be effective in enabling ZK Rollup or supporting cheap fraud proofs in multi-round Optimistic Rollup.
Thus, unfortunately, the functionality loss and complexity increase of using anything other than KZG far outweighs the risks of KZG itself. Furthermore, any risk associated with KZG is contained: a KZG failure would only affect Rollup and other applications that rely on the blob data, not the rest of the system.
How “complex” and “new” is KZG?
KZG commitments were introduced in a 2010 paper and have been widely used in PLONK-style ZK-SNARK protocols since 2019. However, the underlying mathematics of KZG commitments is a relatively simple arithmetic on top of the foundational mathematics of elliptic curve operations and pairings.
The specific curve used is BLS12-381, which was invented by Barreto-Lynn-Scott in 2002. Elliptic curve pairings, which are required to verify KZG commitments, are very complex mathematics, but they were invented in the 1940s and applied to cryptography since the 1990s. By 2001, many cryptographic algorithms using pairings were proposed.
From an implementation complexity point of view, KZG is no harder to implement than IPA: the function to compute the commitment (see above) is exactly the same as in the case of IPA, just with a different set of elliptic curve point constants. The point verification precompile is more complex because it involves pairing evaluation, but the mathematics is identical to what has already been done in the implementation of EIP-2537 (BLS12-381 precompile), and is very similar to the bn128 pairing precompile (see also: optimized Python implementation). Therefore, no complex “new work” is required to implement KZG verification
What are the different software parts of proto-danksharding implementation?
There are four main components:
1. Changes to the execution layer consensus (see EIP for details):
New transaction type containing blobs
Opcode that outputs the versioned hash of the i-th blob in the current transaction
Blob verification precompile
Point evaluation precompile
2. Consensus layer consensus changes (see this folder in the repo):
List of blob KZGs in BeaconBlockBody
A "sidecar" mechanism where the full blob contents are passed together with a separate object from the BeaconBlock
Blob versioned hash in the execution layer and blob KZG in the consensus layer
3. Memory pool
BlobTransactionNetworkWrapper (see the Network section of the EIP)
Stronger anti-DoS protection to compensate for large blob sizes
4. Block construction logic
Accepts transaction wrappers from the memory pool, puts transactions into ExecutionPayload, puts KZG into the beacon block and the body in the sidecar
Deal with the secondary fee market
Note that for a minimal implementation we don’t need a memory pool at all (we can rely on the second layer transaction bundle market), we only need a client to implement the block construction logic. Only consensus changes to the execution and consensus layers require extensive consensus testing and are relatively lightweight. Anything between such a minimal implementation and a “full” deployment where all clients support block production and a memory pool is possible.
What does the proto-danksharding multi-dimensional fee market look like?
Proto-danksharding introduces a multi-dimensional EIP-1559 fee market with two resources, gas and blobs, with separate floating gas prices and separate limits.
That is, there are two variables and four constants:
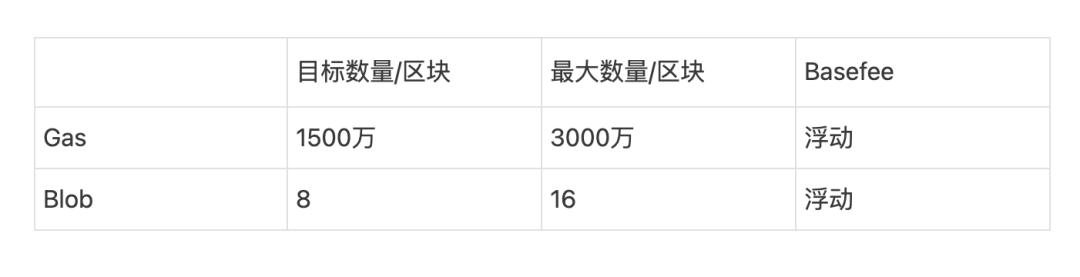
The blob fee is charged in gas, but it's a variable amount of gas that adjusts so that in the long run the average number of blobs per block is effectively equal to the target number.
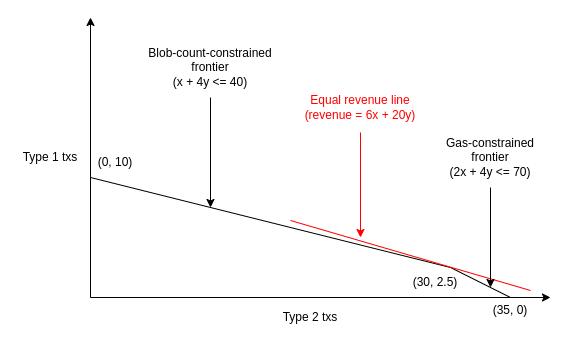
The two-dimensional nature means that block builders will face a harder problem: instead of simply accepting transactions with the highest priority fees until they run out of transactions or hit the block gas limit, they will have to avoid hitting two different limits at the same time.
Here's an example. Suppose the gas limit is 70 and the blob limit is 40. The mempool has a lot of transactions, enough to fill the block, of two types (tx gas includes per-blob gas):
Priority fee 5 per gas, 4 blobs, 4 total gas
Priority fee 3 per gas, 1 blob, 2 total gas
A miner following the naive "lower priority fee" algorithm will fill the entire block with 10 transactions of the first type (40 gas) and receive a revenue of 5 * 40 = 200 gas. Because these 10 transactions fill the blob limit completely, they will not be able to include more transactions. But the optimal strategy is to take 3 transactions of the first type and 28 transactions of the second type. This gives you a block with 40 blobs and 68 gas, and a revenue of 5 * 12 + 3 * 56 = 228.
Do executing clients now have to implement a complex multidimensional knapsack problem algorithm to optimize their block production? No, for several reasons:
EIP-1559 ensures that most blocks will not hit either limit, so only a few blocks actually face the multidimensional optimization problem. In the normal case where the mempool does not have enough (enough paid) transactions to hit either limit, any miner can get the best revenue by including every transaction they see.
In practice, fairly simple heuristics can get close to optimality. In similar cases, see Ansgar's EIP-4488 analysis for some data on this.
Multidimensional pricing isn’t even the biggest revenue stream from specialization — MEV is. Dedicated MEV revenue extracted from on-chain DEX arbitrage, liquidations, front-running NFT sales, etc. via specialized algorithms accounts for a large portion of total “extractable revenue” (i.e., priority fees): dedicated MEV revenue appears to average around 0.025 ETH per block, with total priority fees typically around 0.1 ETH per block.
The Proposer/Builder Separation is designed around highly specialized block production. PBS turns the block-building process into an auction, where specialized participants bid for the privilege of creating a block. Regular validators simply accept the highest bid. This is intended to prevent MEV-driven economies of scale from creeping into validator centralization, but it handles all of the issues that would make optimizing block building more difficult.
For these reasons, more complex fee market dynamics do not greatly increase centralization or risk; in fact, the principles more broadly applied can actually reduce the risk of DoS attacks!
How does the exponential EIP-1559 blob fee adjustment mechanism work?
Today's EIP-1559 adjusts the base fee b to reach a specific target gas usage level t, like this:
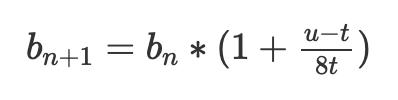
Where b(n) is the base fee of the current block, b(n+1) is the base fee of the next block, t is the target, and u is the gas used.
A big problem with this mechanism is that it doesn't actually target t. Suppose we get two blocks, the first with u=0 and the next with u=2t. We get:
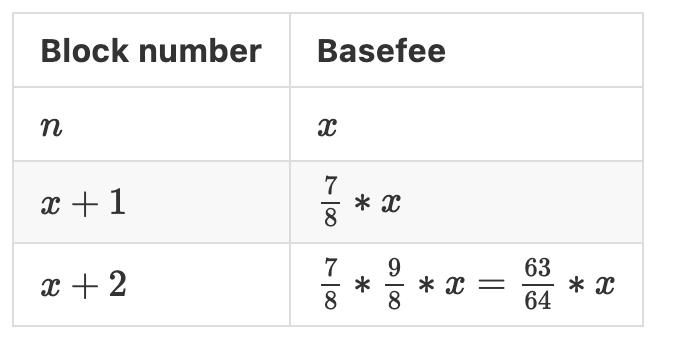
Despite average usage being equal to t, the base fee has dropped by 63/64. So basefee is only stable if usage is slightly above t; in practice it is apparently about 3% higher, although the exact number depends on variance.
A better formula is an exponential adjustment:
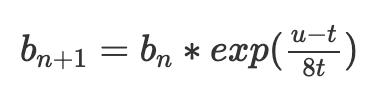
exp(x) is the exponential function e^x, with e2.71828. For small values of x, exp(x)1+x. However, it has a convenient property that is independent of transaction permutations: multi-step adjustment

depends only on the sum u1+...+u/n, not on the distribution. To see why, we can do the math:
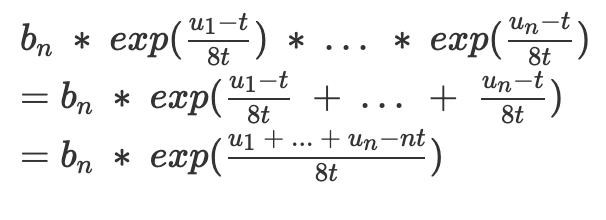
Thus, the same transactions included will result in the same final base fee, no matter how they are distributed between different blocks.
The last formula above also has a natural mathematical interpretation: the term (u1+u2+...+u/n-nt) can be seen as redundant: the difference between the total gas actually used and the total gas intended to be used.
The fact that the current basefee is equal to
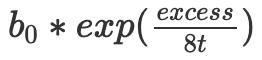
makes it clear that the excess cannot exceed a very narrow range: if it exceeds 8t60, then the basefee becomes e^60, which is ridiculously high and no one can afford it, and if it is below 0, then resources are essentially free and the chain will be spammed until the excess is back above zero.
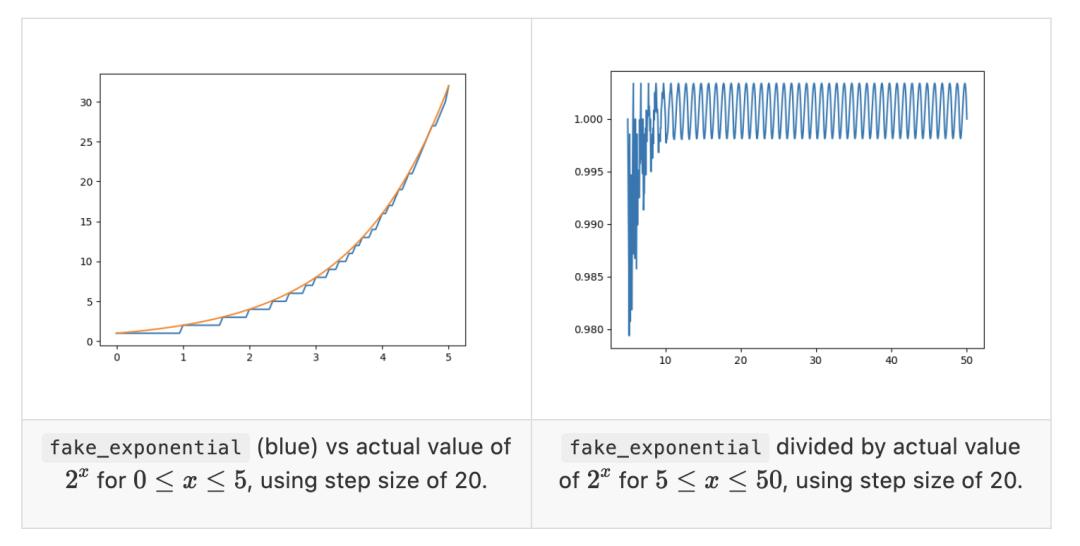
The adjustment mechanism works exactly in these terms: it keeps track of the actual total (u1+u2+...+u/n) and calculates the target total (nt), and calculates the price as the exponential of the difference. To make the calculation simpler, we don't use e^x, but 2^x; in fact, we use an approximation of 2^x: the fake_exponential function from the EIP. The fake exponential is almost always within 0.3% of the actual value.
To prevent long periods of underuse from causing long periods of 2x full blocks, we added an additional feature: we don't let excess blocks go below zero. If actual_total is below targeted_total, we simply set actual_total equal to targeted_total. In extreme cases (blob gas drops all the way to zero) this does break transaction order invariants, but the added security makes this an acceptable tradeoff. Also note an interesting consequence of this multi-dimensional market: when proto-danksharding was initially introduced, there were probably very few users at first, so for a while the cost of a blob would almost certainly be very cheap, even if "regular" Ethereum blockchain activity was still expensive.
The author believes that this fee adjustment mechanism is better than the current approach, so eventually all parts of the EIP-1559 fee market should move to using it.
For a longer and more detailed explanation, see Dankrad’s post.
How does fake_exponential work?
For convenience, here is the code for fake_exponential:
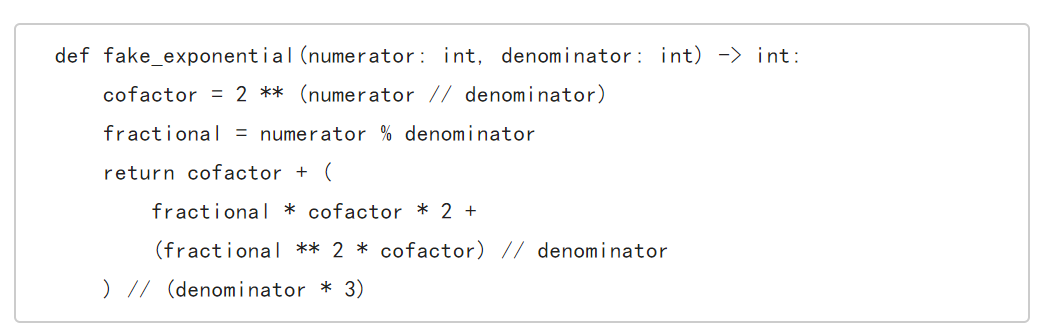
Here is the core mechanism restated mathematically, with rounding removed:

The goal is to stitch together many instances of (QX), one that is appropriately shifted and scaled for each [2^k,2^(k+1)] range. Q(x) itself is a 2^x approximation of 0x1, chosen for the following properties: - simplicity (it’s a quadratic equation) - correctness on the left edge (Q(0)=2^0=1) - correctness on the right edge (Q(1)=2^1=2) - smooth slope (we make sure Q′(1)=2Q′(0), so each shifted+scaled copy of Q has the same slope on its right edge as the next copy on its left edge) The last three require three linear equations with three unknown coefficients, and the Q(x) given above gives a unique solution.
The approximation is surprisingly good; for all but the smallest inputs, fake_exponential gives an answer that is within 0.3% of the actual value of 2^x:
What issues are still being debated in proto-danksharding?
Note: This section can easily become out of date. Don’t trust it to give the latest thinking on any particular issue.
All major Optimistic Rollups use multiple rounds of proofs, so they can use (much cheaper) point-evaluation precompiles instead of blob-verification precompiles. Anyone who really needs blob-verification can implement it themselves: take a blob D and a versioned hash h as input, choose x=hash(D,h), compute y=D(x) using barycentric evaluation, and verify h(x)=y using a point-evaluation precompile. So do we really need the blob validation precompilation or can we just remove it and use only dot evaluation?
How capable is the chain at handling durable, long-lived 1MB+ blocks? If the risk is too great, should the target blob count be reduced in the beginning?
Should blobs be denominated in gas or ETH (which gets burned)? Should there be other adjustments to the fee market?
Should new transaction types be treated as blobs or SSZ objects, changing the ExecutionPayload to a union type in the latter case? (This is a “more work now” vs. “more work later” tradeoff)
The exact details of the trusted setup implementation (technically out of scope for the EIP itself, as this setup is “just a constant” to implementors, but still needs to be done).
Original link
Welcome to join the official BlockBeats community:
Telegram Subscription Group: https://t.me/theblockbeats
Telegram Discussion Group: https://t.me/BlockBeats_App
Official Twitter Account: https://twitter.com/BlockBeatsAsia
 Related Articles