AI Computing Power Financialization: Open-Source Models Are Bringing Computing Power to the Capital Market (Part 1)
This article is a in-depth research report produced by OKX Ventures. Due to its length, it is divided into two parts for publication: the first part focuses on hashrate securitization, risk exposure, and derivative pricing logic; the second part will analyze in-depth hashrate financial infrastructure, inference asset opportunities, and industry trends. This article is the first part.
Introduction: Hashrate Securitization and Risk Exposure
The AI infrastructure is entering a capital-intensive expansion phase, and the economic nature of hashrate is also changing accordingly. In the past, enterprises mostly viewed hashrate as an IT cost to be procured on-demand; now, GPUs, data center capacity, and multi-year procurement contracts are increasingly appearing on the balance sheet as assets, and hashrate is beginning to exhibit the characteristics of a capital asset: significant upfront investment, a multi-year payback period, and future revenue and equipment value subject to supply-demand dynamics and technological iterations.
GPU procurement and data center construction are also becoming more reliant on debt financing. Today's GPU credit can already be secured by equipment collateral and long-term customer contracts, but the market still lacks open, standardized GPU-hour forward prices and hedging tools. Debt repayment needs to follow a set schedule, and how much rent these GPUs can fetch and how much they will be worth in a few years will depend on the market conditions at that time. The higher the leverage, the greater the impact of this price uncertainty on debt servicing and refinancing.
Section One: Background - Capital Structure of the Hashrate Market
1.1 Hashrate Expansion Entering Leverage Stage
One of the most notable changes in AI infrastructure in recent years is that capital expenditure has started to outpace internal cash flow expansion. From 2020 to 2023, the AI-related CapEx of the Top 5 cloud providers as a percentage of operating cash flow was still around 20%-30%, but by 2025, it had reached close to 94%. By 2026, the confirmed CapEx scale of the Top 5 cloud providers exceeds $700 billion collectively.
These companies still have strong cash generation capabilities, but as infrastructure construction expands over the long term at a scale of trillions of dollars, debt capital will naturally play a larger role. A separate financing logic for hashrate assets is beginning to take shape.
GPUs, servers, and data centers require capital investment before generating revenue, and hashrate operators like Neocloud usually do not have the strong credit of Hyperscalers. Lenders are therefore increasingly basing their financing decisions on the project itself: whether future cash flows are stable enough to cover debt service, how much asset value can be recovered in the event of default, and more.
The Take or Pay long-term contract is key to the viability of this structure. Even if the customer does not fully utilize the reserved capacity, they are still required to pay the agreed-upon fee according to the contract. For the operator, this is equivalent to pre-emptively locking in a portion of future revenue; for the lender, it transforms the highly uncertain GPU utilization into a more predictable contractual cash flow.
CoreWeave is the most typical example of this model (with over 98% of its revenue coming from Take or Pay contracts). As the proportion of long-term contracts with investment-grade customers increases, its financing relies more and more on the creditworthiness of off-takers and contract coverage. Operators like Nebius and IREN, with large customer long-term contracts, have subsequently adopted similar structures.
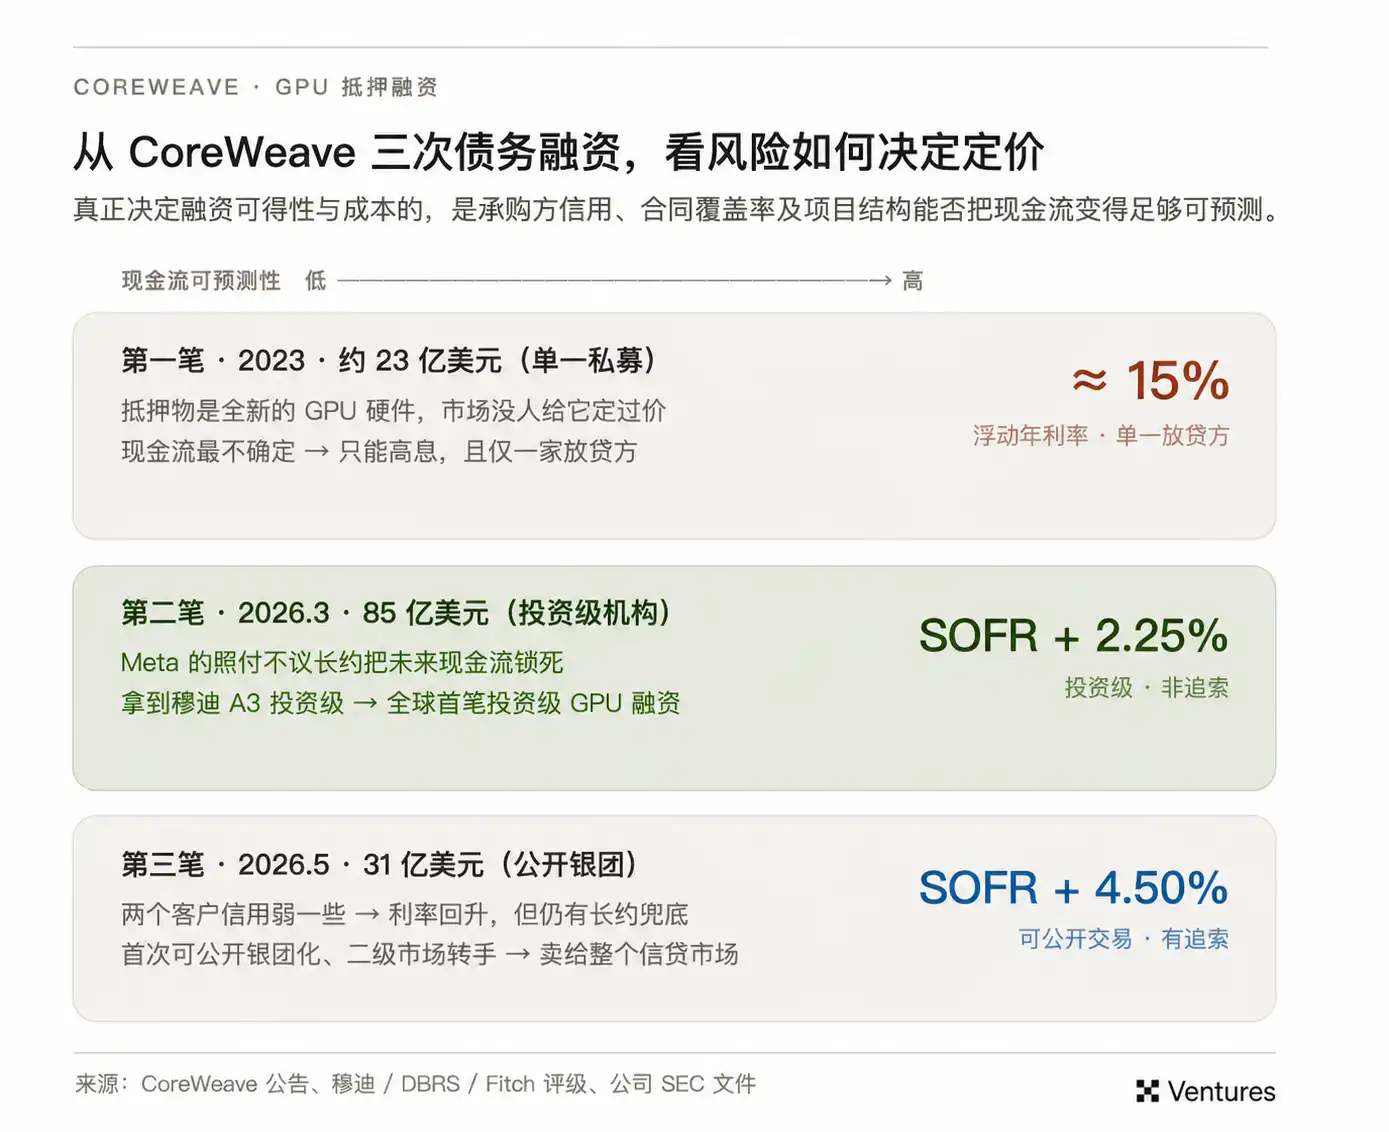
This has shifted the risk assessment of GPU credit. Lenders first assess whether the contractual cash flow can cover the debt, and then evaluate how much can be recovered post-default. The number of GPUs determines the scale of the collateral, while long-term orders further determine the financing terms these assets can obtain.
1.2 After the cash flow is locked in, what remains is asset price risk.
While Take or Pay increases the visibility of debt repayment cash flow, the economic value of the GPUs themselves continues to fluctuate. Years later, how much revenue these devices can still generate and how much they are worth remain risks that stay on the balance sheet.
GPUs possess attributes of both production equipment and technological products. They can continuously generate rent but are subject to a rapid technological iteration cycle. After the next generation of chips is launched, the impact on the previous-generation equipment will gradually be reflected in rent, utilization rates, renewal prices, and secondary market value.
Therefore, the accounting depreciation of GPUs and their economic depreciation are difficult to reconcile completely. While accounting can amortize equipment costs over a fixed period, the market reassesses every day how much competitive computing power a GPU can still produce. For lenders, the core variables ultimately boil down to the cash flows within the remaining loan term and how much value can be recovered in the event of default. (There have been market concerns regarding the depreciation policies around data center assets of large cloud providers)
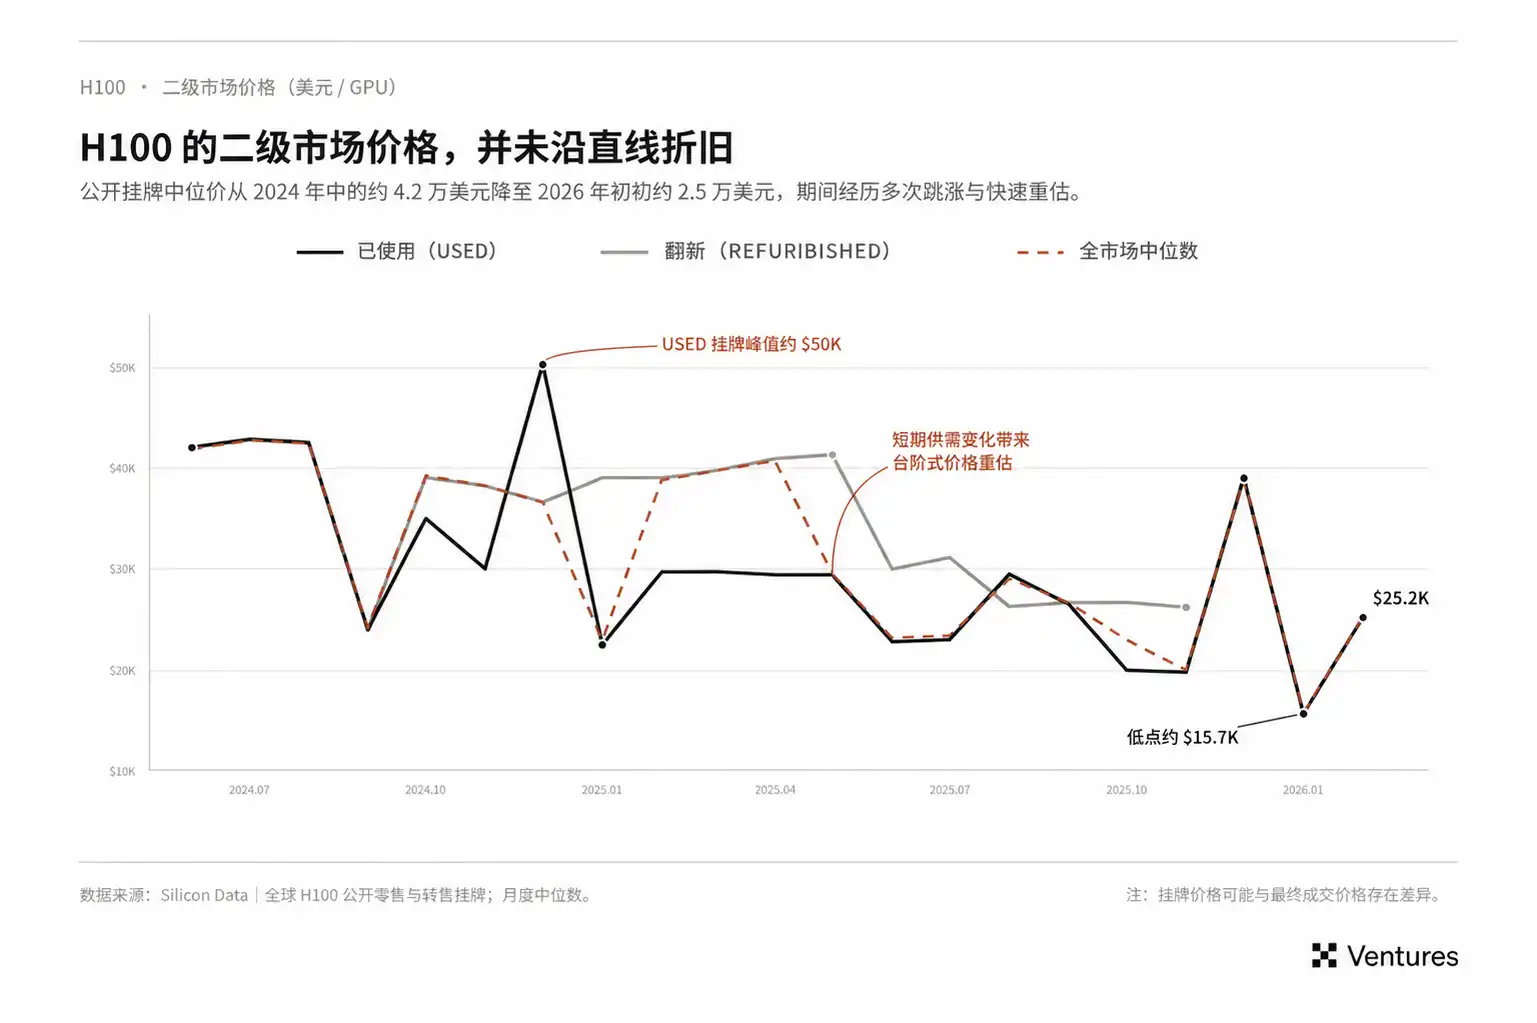
This also explains why the current GPU credit can maintain stability temporarily when rental prices drop. As long as the lessee continues to perform, spot price changes may not immediately affect current debt repayment; the risk is more concentrated at several points such as contract renewal, refinancing, and default disposal. At these points, the market rent and residual value of the GPU will reevaluate the loan's cushion.
If rent and equipment value decline faster than the loan principal amortization, the LTV will rise again, narrowing the loan's cushion. Long-term contracts can push the risk further back but cannot lock in the economic value of the equipment throughout its entire lifecycle.
The gap in the current computing power credit structure is thus very clear: contracts lock in a portion of customer payments, while the GPU's market price continues to fluctuate.
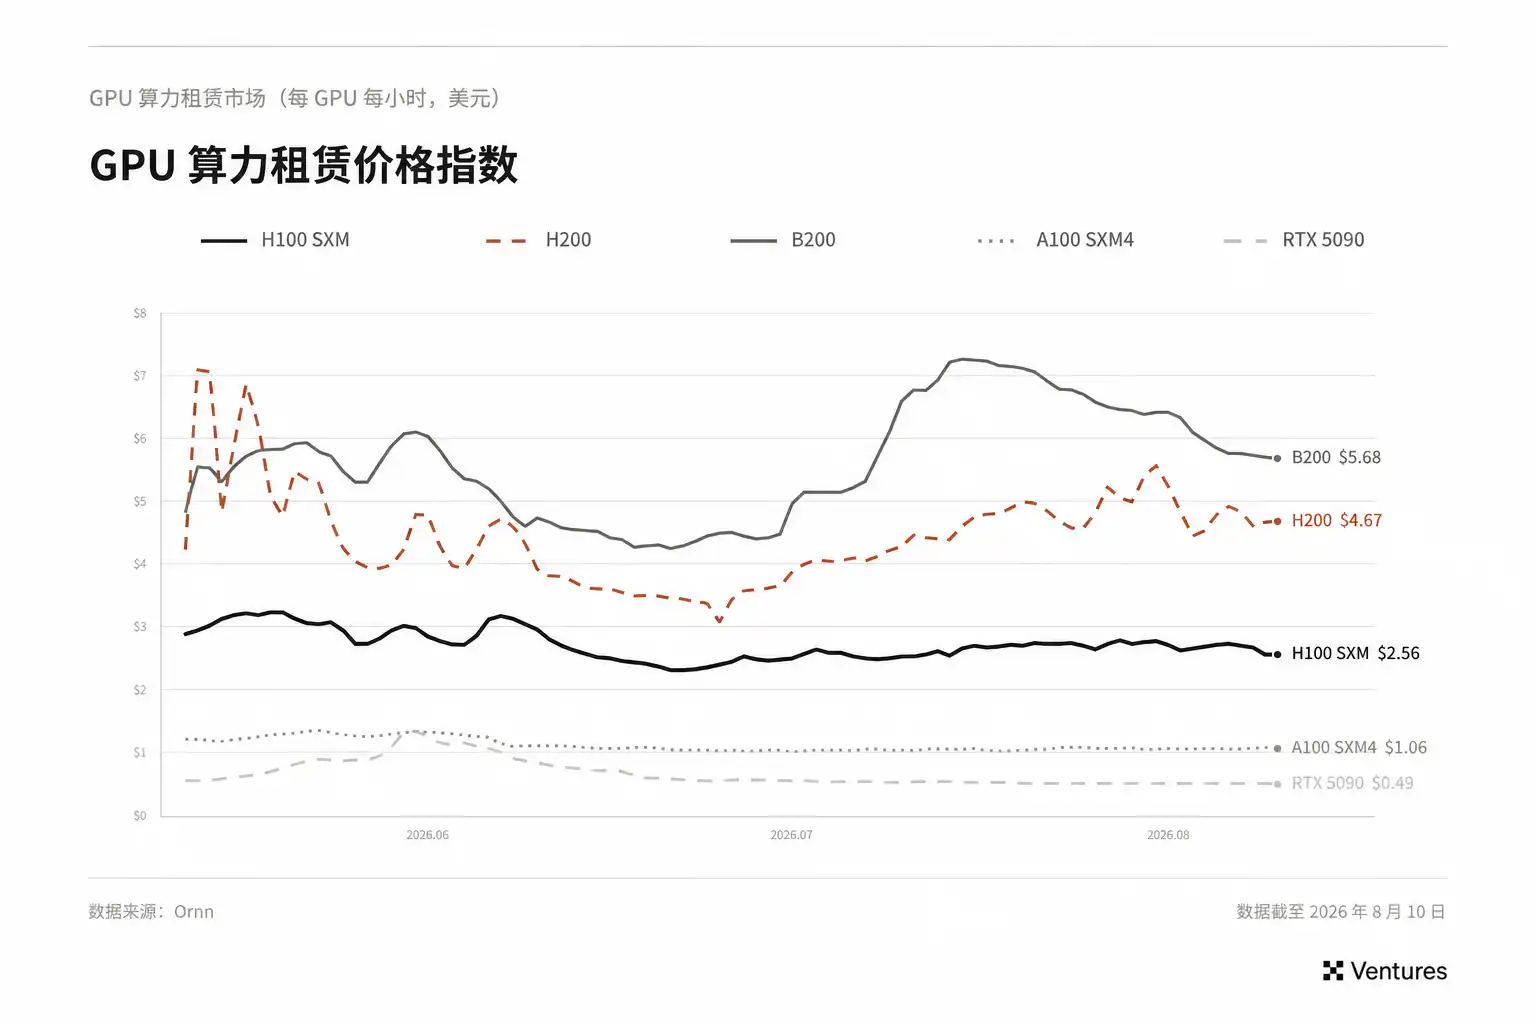
The market currently relies primarily on long-term capacity contracts to lock in prices in advance. Early H100 one-year contracts had a significant discount relative to spot, but as spot prices declined and forward contract prices rose, the price difference between the two has narrowed significantly. Supply improvements and changes in contract terms will affect this result, but it also reflects a more fundamental issue: in the absence of standardized forward, futures, and swaps tools, industry participants can only let long-term physical contracts fulfill both procurement and price management functions simultaneously.
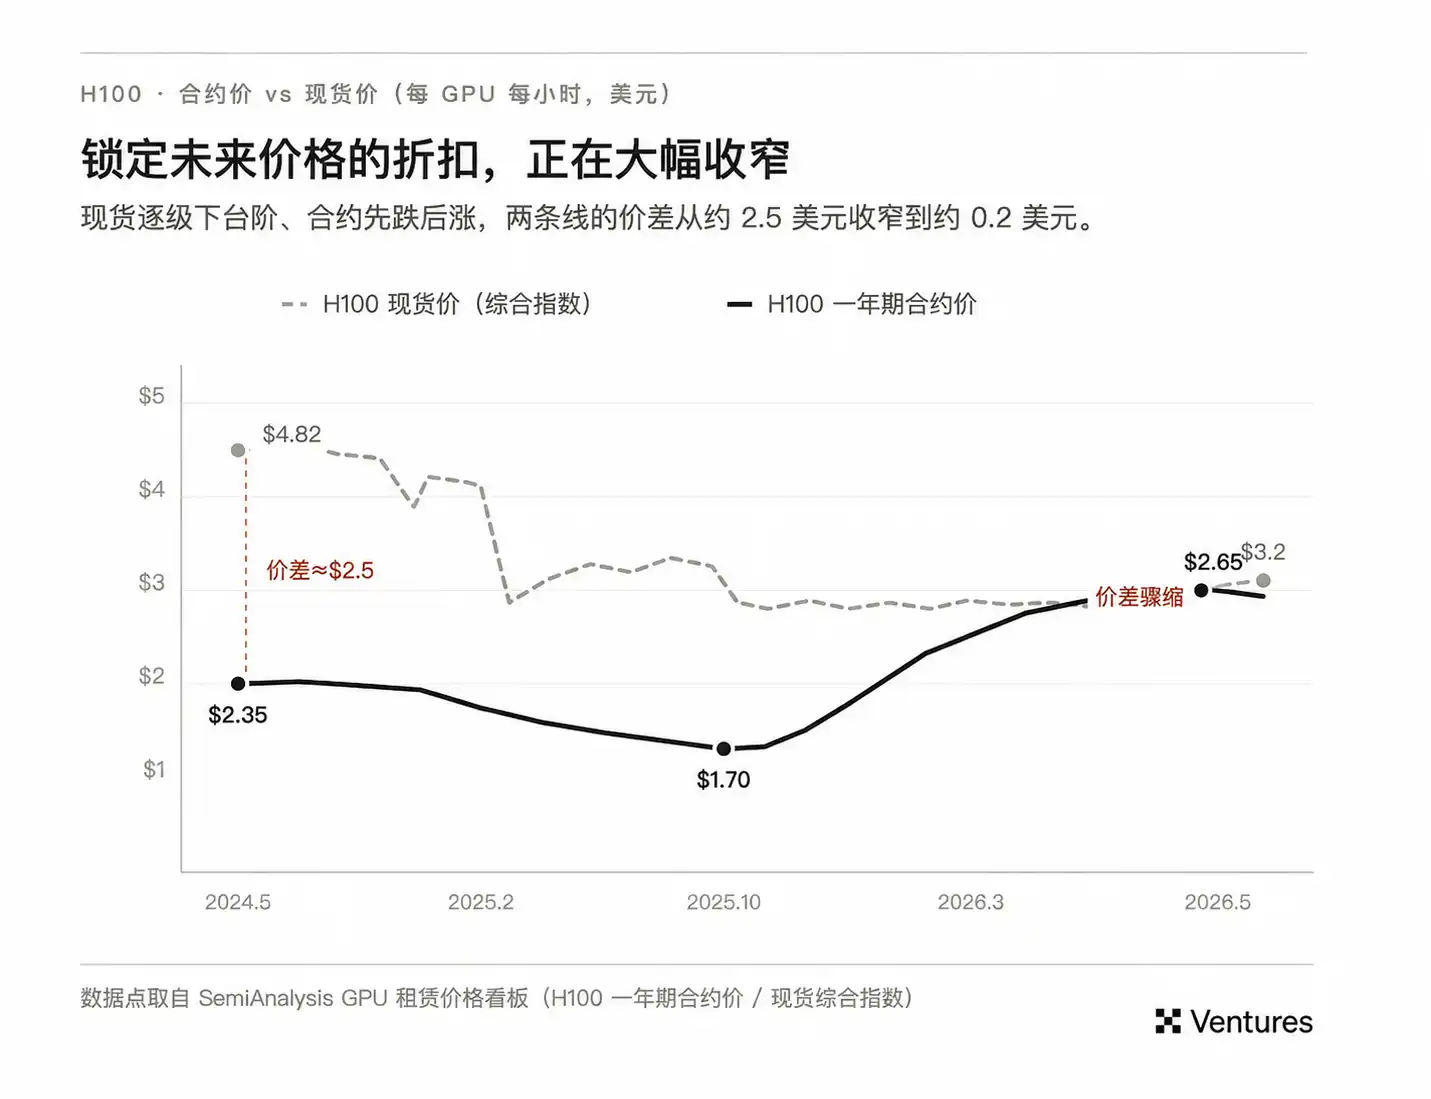
Long-term contracts can achieve risk allocation between individual transaction counterparties; when the market needs to continuously form public prices and transfer risk across institutions, further standardization of financial tools is needed. As more and more GPU assets are supported by debt capital, this demand will become increasingly apparent.
II. What Does the Computing Power Market Really Need to Trade?
Once computing power enters the capital structure, price fluctuations begin to have clear counterparties. Neocloud holds the risk of rental price drops, AI companies hold the risk of rising procurement costs, and creditors hold the risk of residual value and refinancing. The derivatives market often truly forms from these risks that the balance sheet cannot digest on its own.
2.1 Three Types of Participants and Their Risk Exposure
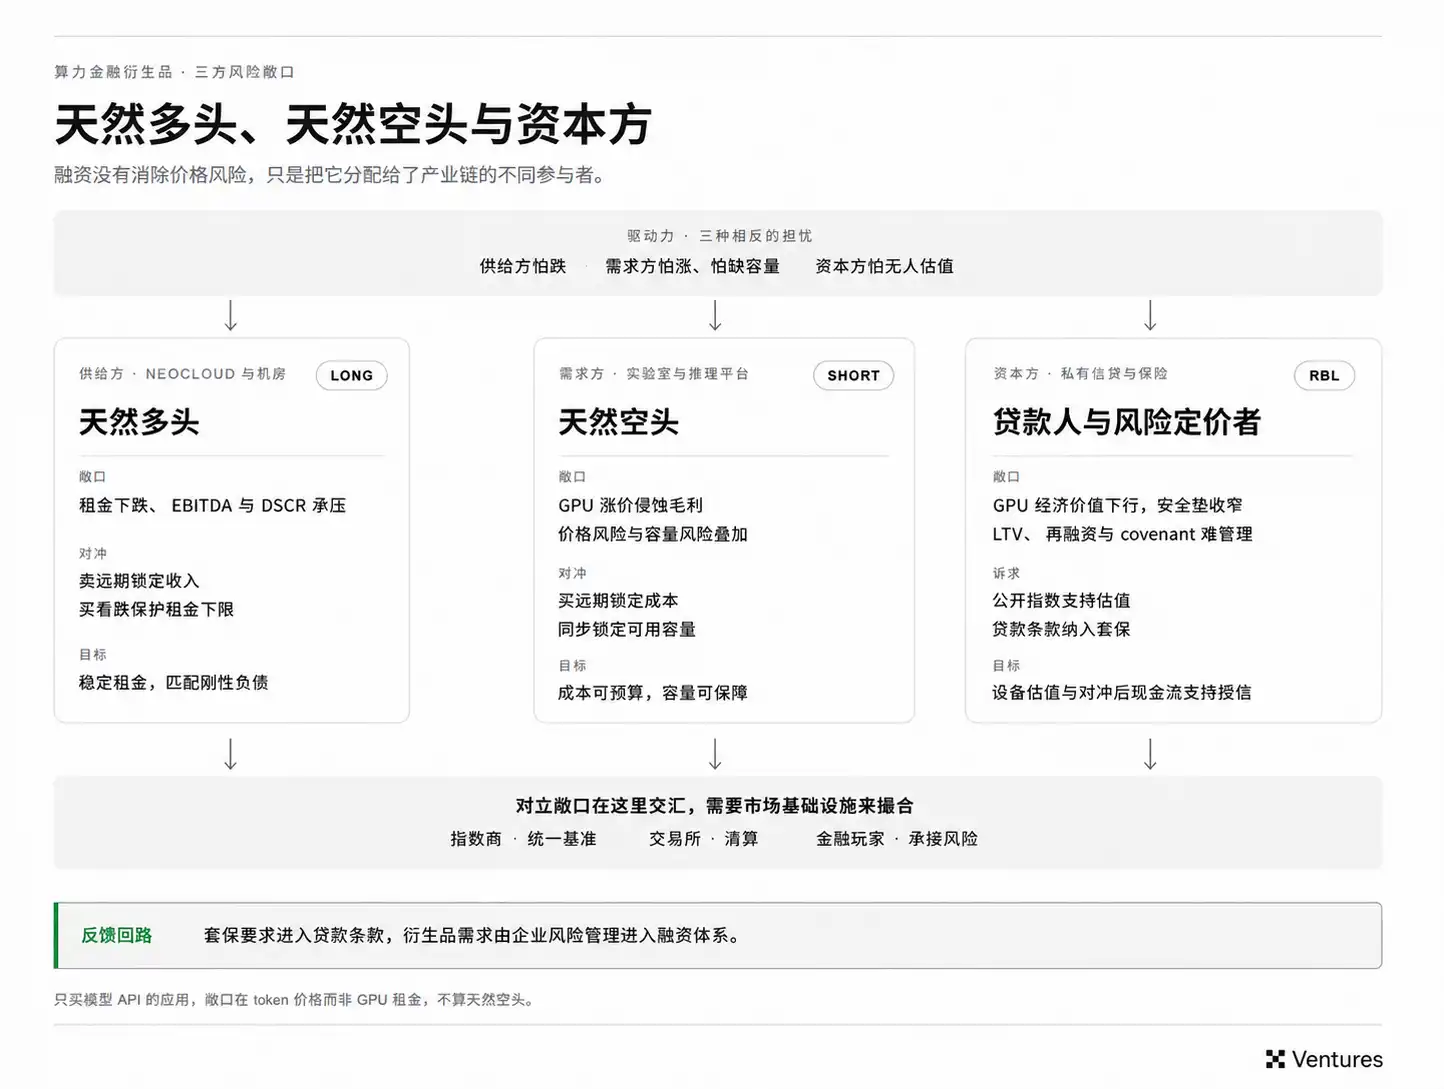
Computing power price fluctuations will ultimately impact three types of balance sheets. Neocloud has locked in GPU, data center, and financing costs upfront, but future rents will still be repriced; when insufficiently covered by long-term contracts, a rental price drop will quickly compress EBITDA and DSCR, making it most compelling to sell forward and lock in revenue in advance. On the other side are AI labs and reasoning platforms; a GPU price increase will directly erode gross margin, and when the market is tight, price and capacity risks often occur simultaneously, requiring them to lock in costs and available capacity simultaneously. Lenders are more concerned about how much cushion is left between the loan balance and the economic value of the GPU; lacking a public index and forward curve, managing LTV, refinancing, and covenants dynamically is challenging. As hedging requirements gradually enter loan terms, the demand for computing power derivatives will also shift from companies proactively managing risk to further entering the financing system.
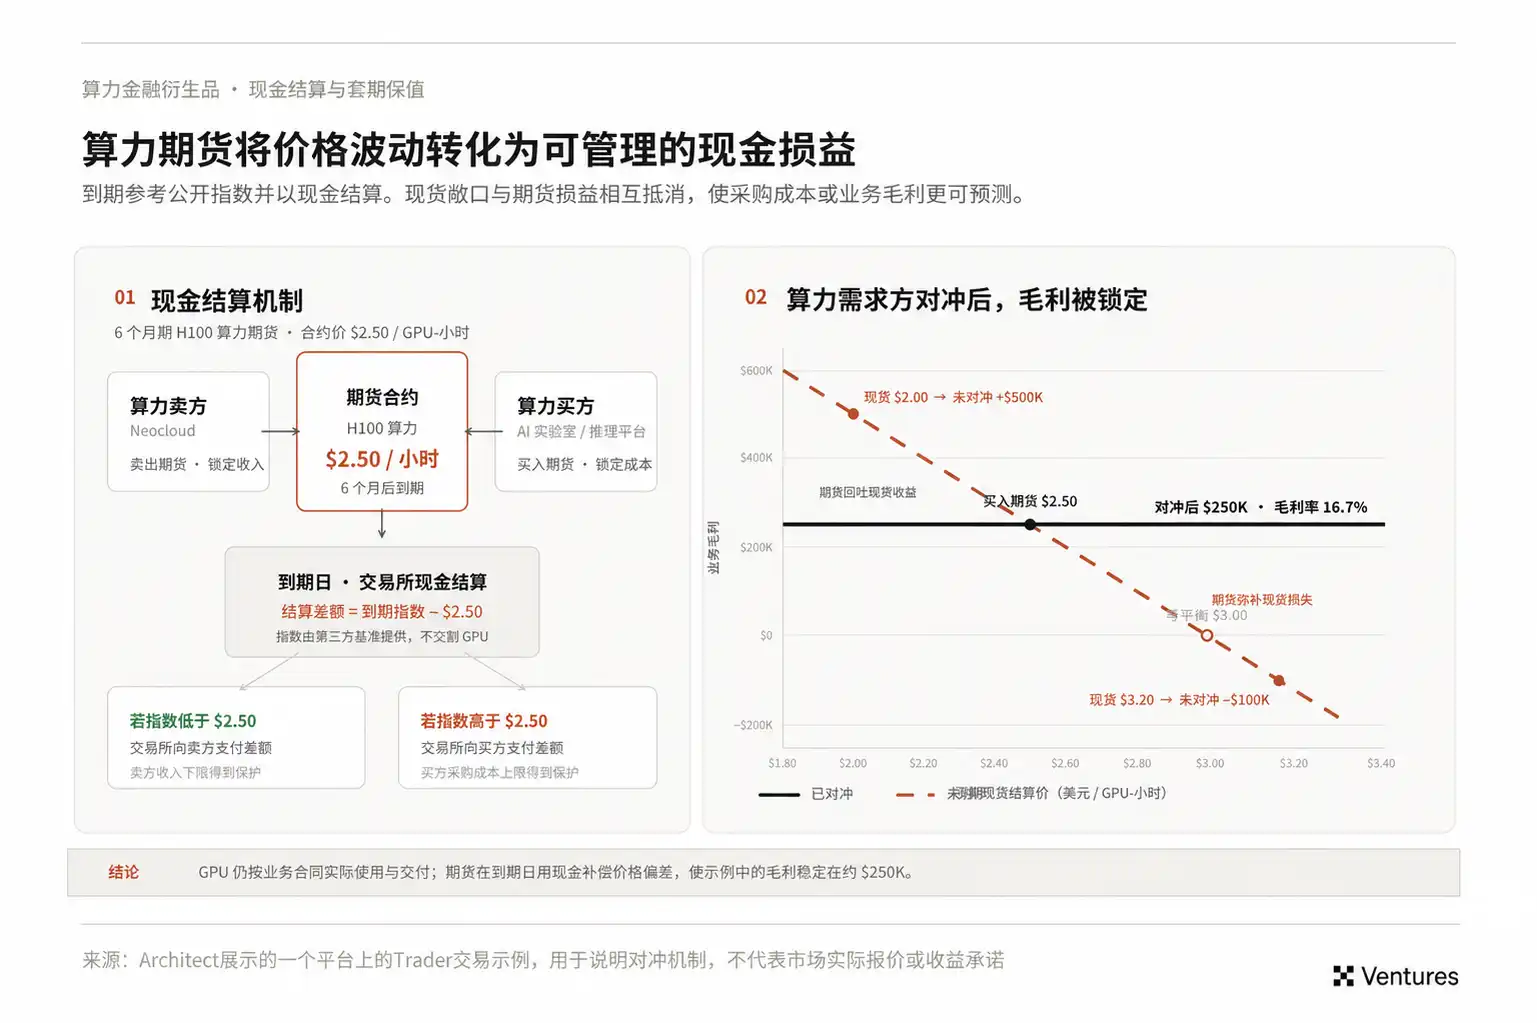
2.2 Potential Market Size: What Risk Exposures Will Enter the Derivatives Market
If we directly use the global GPU shipment volume, data center CapEx, or AI infrastructure scale to estimate the compute derivatives TAM, the result is likely to be easily an order of magnitude higher.
What can truly enter the derivatives market is the portion of risk that is still exposed to market prices and has not been absorbed in other ways.
A large portion of the risk of hyperscaler self-built GPUs used internally remains on their own balance sheets; the capacity already under multi-year fixed-price contracts has also had the price risk allocated in advance in bilateral contracts. They all have economic risks, but may not necessarily need to enter the market for trading every day.
Therefore, from global compute demand to the actual derivatives TAM, there needs to be at least several layers of filtering in between:
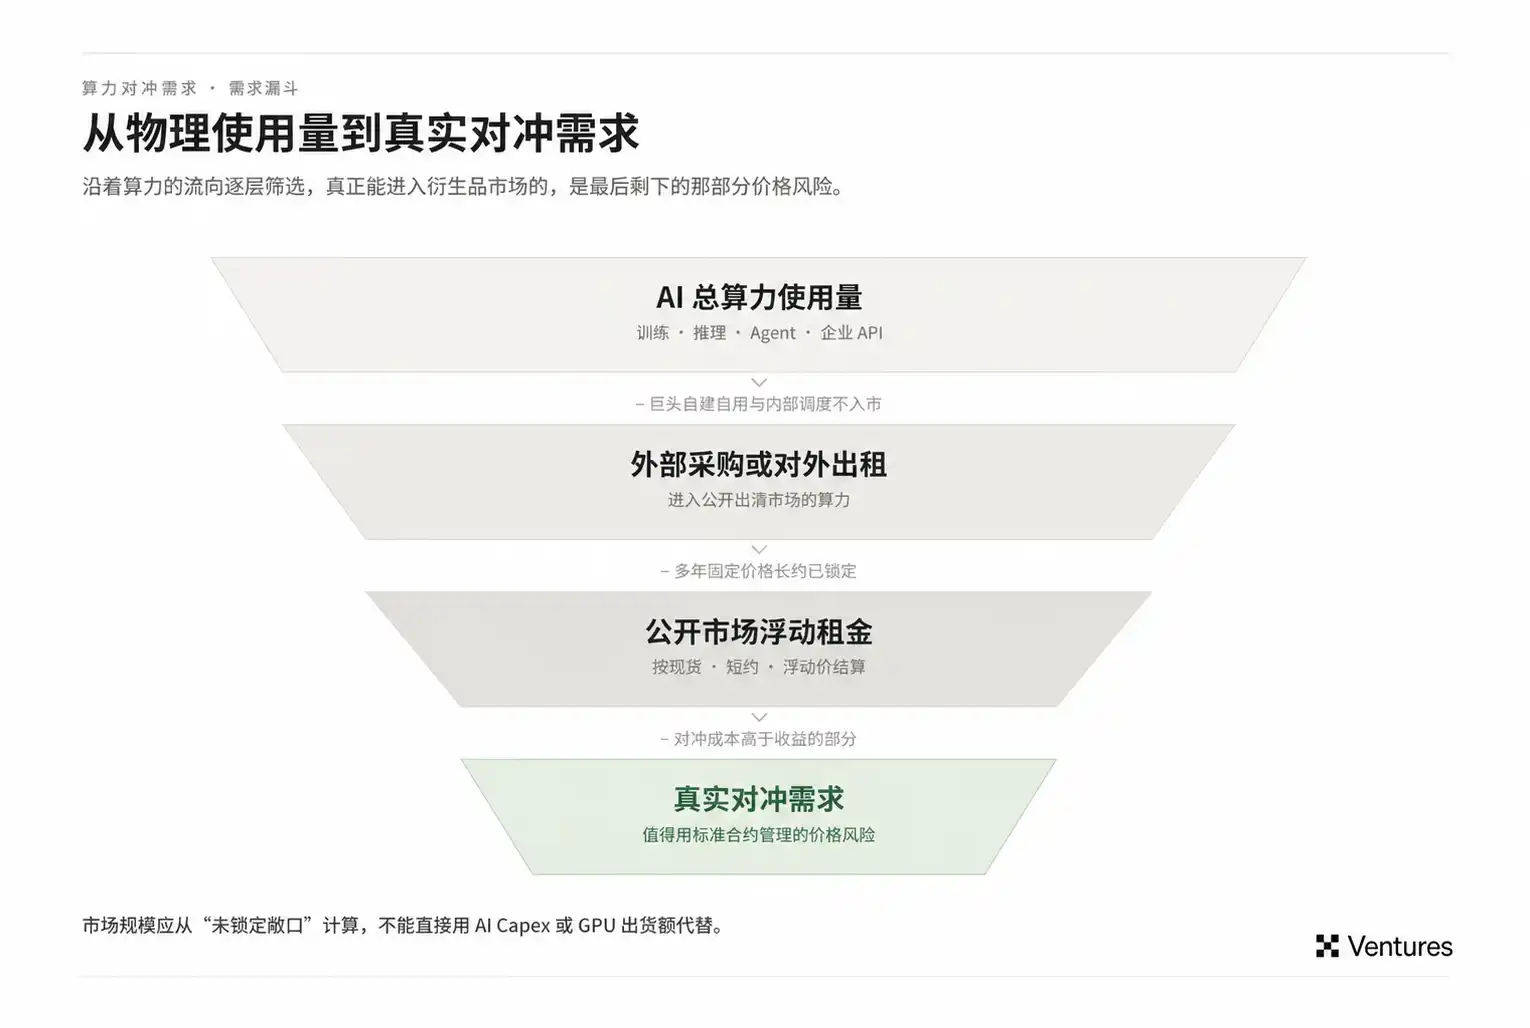
This is also why the size of the future compute derivatives market is likely more closely related to the share of merchant compute, rather than a simple linear growth based on global GPU installations.
In the past, a large number of advanced models ran in a few large labs and hyperscalers internally, with compute procurement similarly highly internalized. As open-source model performance improves, more and more enterprises can deploy on their own, or hand over workloads to third-party Neocloud and inference platforms. The compute demand that was originally locked within a few large balance sheets will gradually transform into public market purchasing orders. This also explains why the development of open-source models is worth paying attention to:
First, more compute power is beginning to establish real transaction prices. Without a sufficient number of external transactions, it is difficult to form an index, let alone discuss a forward curve.
Second, demand shocks will propagate faster to the spot market. After a popular model is released, if a large number of enterprises simultaneously increase deployment, the new demand will directly impact third-party GPU capacity, and prices and availability will change rapidly. The more marginal demand the public market takes on, the more likely rent fluctuations will become a P&L risk that enterprises truly need to manage.
Therefore, the true significance of open-source models for the securitization of compute lies in their potential to increase the proportion of market-based procurement. Compute power will only gradually form a price worthy of indexing, forward pricing, and securitization through a sufficient number of external transactions. The variables that ultimately determine the size of the compute derivatives market include 1) how much compute enters the public market, 2) how much price remains volatile, and 3) how much risk cannot continue to remain on the original balance sheets.
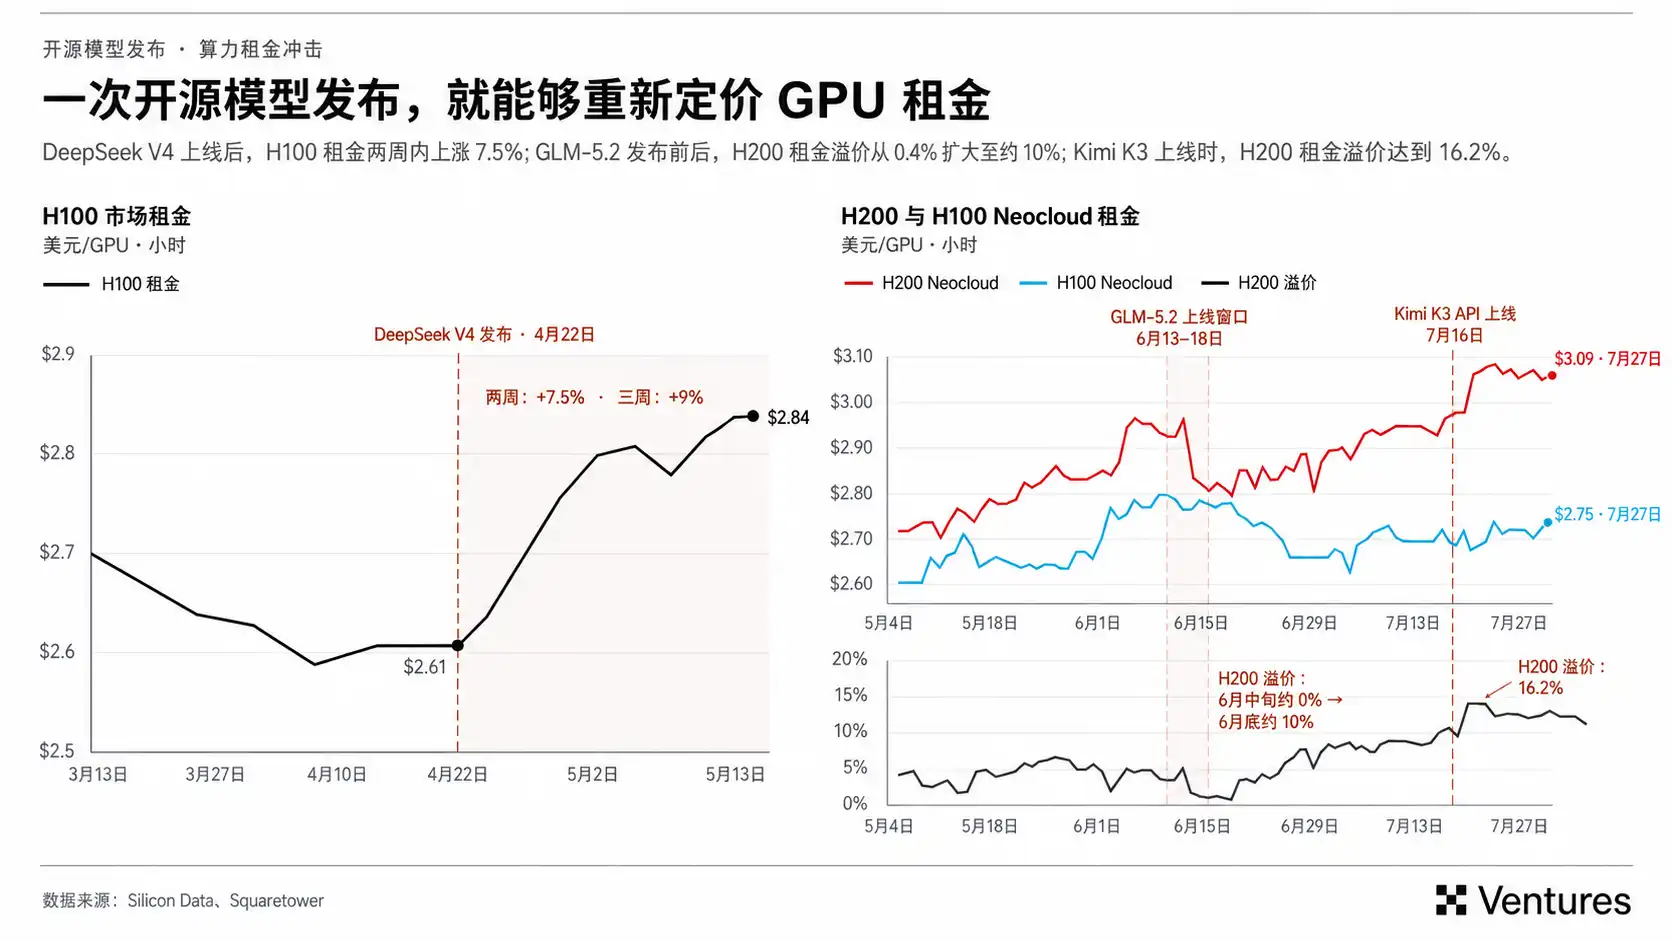
After the release of DeepSeek V4, the rent for H100 increased by about 7.5% within two weeks; both Kimi K3 and GLM 5.2 launches also led to a similar strengthening trend in the rent for H100 and H200. Popular open-source models often bring a large amount of deployment and inference demand in a short period of time. When these new workloads are mainly handled by Neocloud and third-party inference platforms, the market usually experiences a decrease in availability, queuing, and quota tightening, which is then reflected in on-demand rent.
III. Product and Pricing: How to Price Future Computing Power?
The challenge with computing power futures is that the market has not yet formed a sufficiently reliable term price curve.
GPU-hour cannot be stored. An idle H100 today will permanently disappear after the time window has passed, and it is also not possible to buy cheaply in the spot market today and hold for delivery six months later. The traditional spot-futures linkage established through inventory arbitrage is much weaker in the computing power market.
This means that the price at which GPUs should trade six months from now will be more dependent on factors such as chip deliveries at that time, data center and power supply, model efficiency, and actual order intensity. Hardware delays can quickly tighten future capacity, while software optimizations can release a significant amount of effective computing power without increasing the number of GPUs. A computing power futures curve incorporates the market's assessment of hardware supply, energy constraints, and algorithmic advancements.
3.1 Without Inventory Arbitrage, Future Prices Depend More on Expectations and Order Flow
The term structure of the oil market has a relatively stable inventory arbitrage constraint. When the future price is significantly higher than the spot price plus financing and storage costs, traders can buy spot, hold inventory, and sell futures, making it difficult for the spread to deviate significantly from holding costs in the long term.
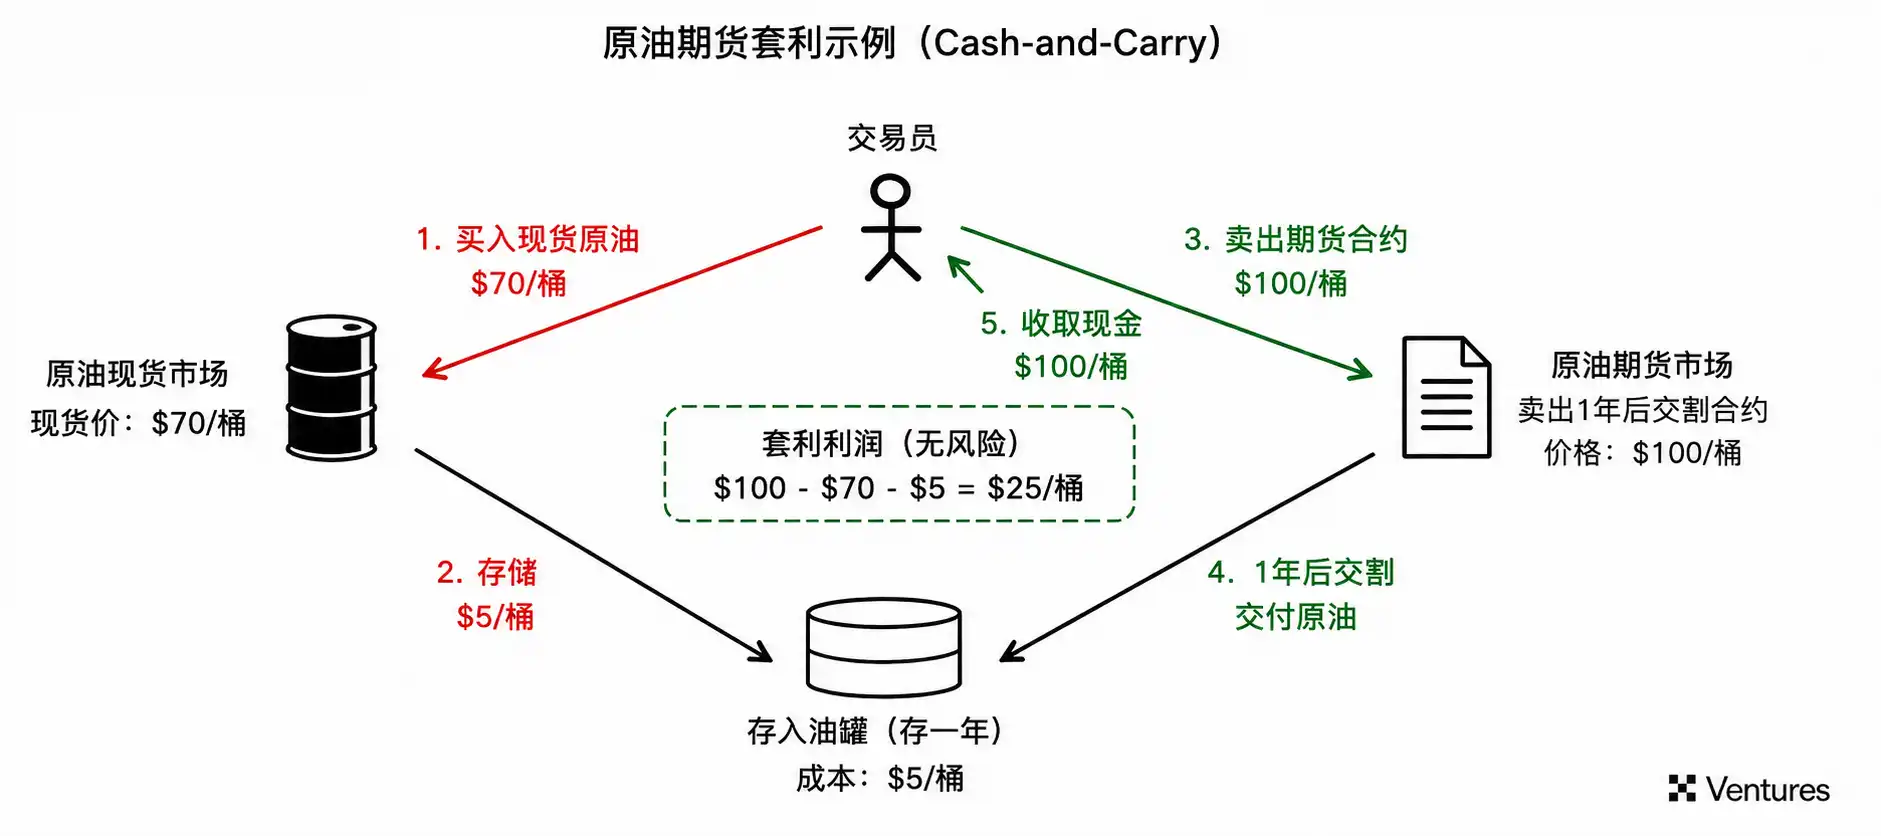
Computing power lacks this layer of cash and carry arbitrage constraint, making the spot price less constraining on the futures curve.
Future prices are therefore very sensitive to marginal information. Blackwell delays in delivery, data center power delays, will reduce expected supply; model distillation, inference optimization, or the increased efficiency of next-generation chips per unit of computation will increase the net effective computing power. Many changes could rewrite the supply and demand balance in a matter of months.
This also increases the value of real order flow. Public spot prices can only tell the market what happened today, while long-term capacity orders can expose future supply and demand earlier. A broker or dealer consistently matching Neocloud and AI Lab transactions can see which data centers are starting to have spare capacity, and which buyers are willing to pay a premium for GPUs six months down the line. This type of information will ultimately directly influence future pricing.
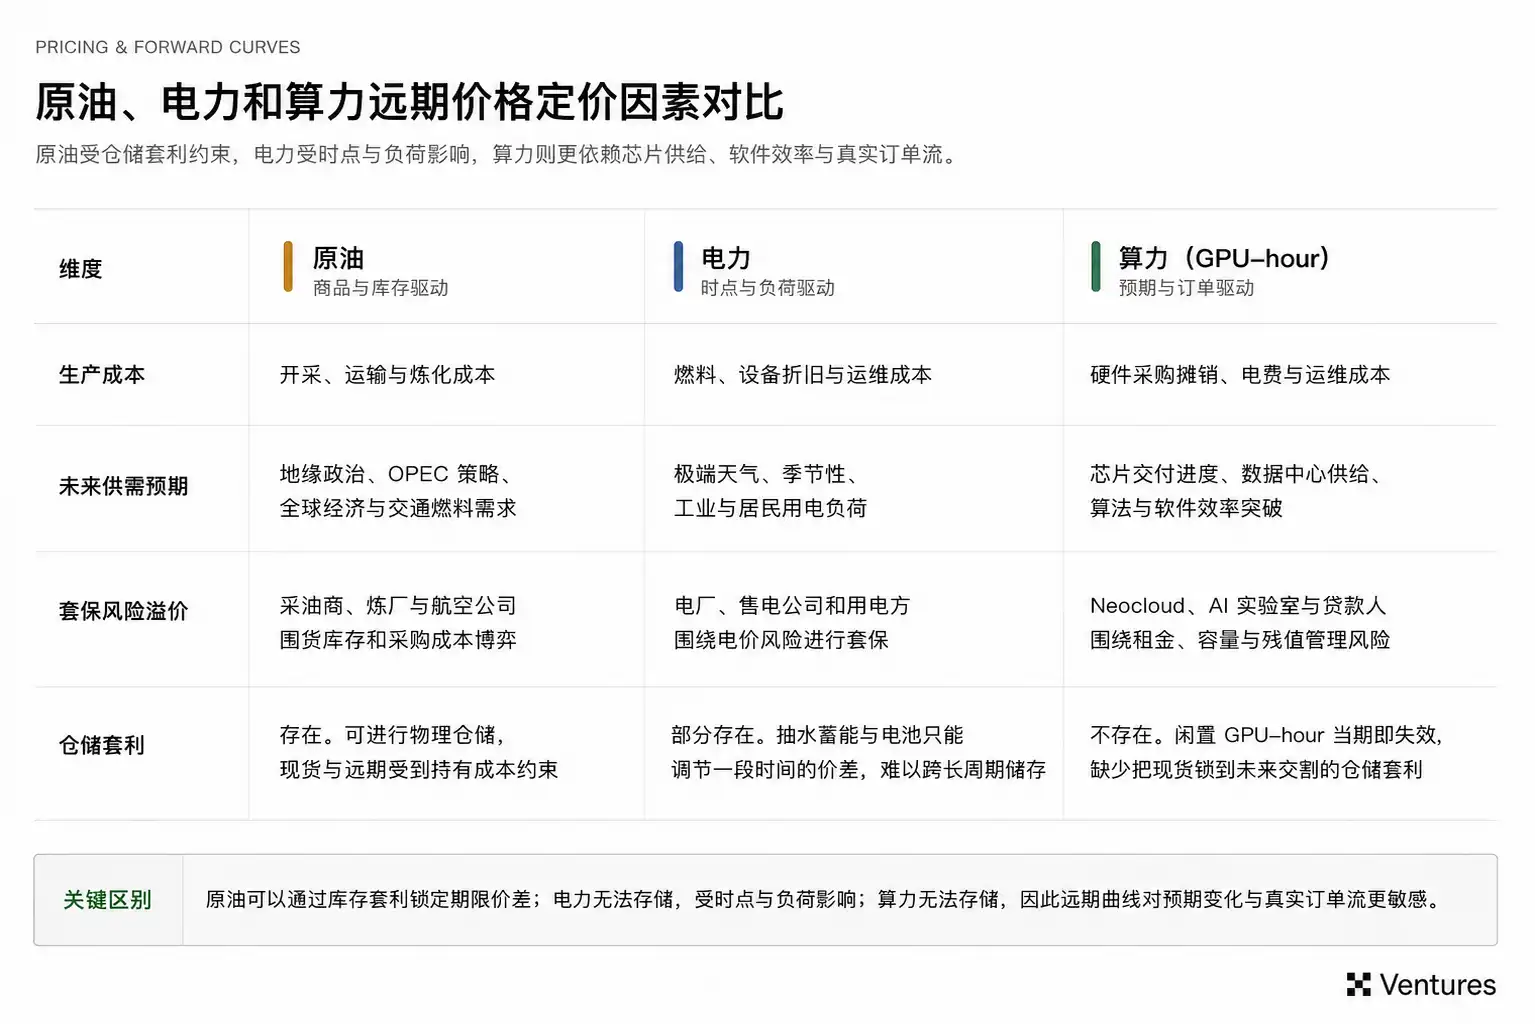
Therefore, the value of the hash rate index lies in compressing highly dispersed non-standard quotes into a set of price benchmarks that can be referenced by contracts, credit, and derivatives. If an index can consistently enter into long-term capacity contracts, loan valuations, OTC settlements, and futures deliveries, it will gradually become a pricing anchor used collectively by the entire market. Whether index providers and dealers can establish barriers will largely depend on how close they are to actual transactions and future orders.
3.2 GPU-Hour and AI Token Financialization Rhythms Will Not Sync
There are actually two layers of pricing in the AI industry chain. Upstream, GPUs are sold based on capacity, midstream inference platforms convert GPU hours into model calls, and then sell AI Tokens, APIs, or specific workloads downstream.
For the inference platform, operating profit depends on both ends. An increase in GPU rental prices will raise input costs, while a decrease in AI Token prices will lower revenue. If both ends have tradable prices, the inference platform can theoretically lock in a compute-to-intelligence spread, which is similar to the logic of refiners managing the crack spread in the energy market.
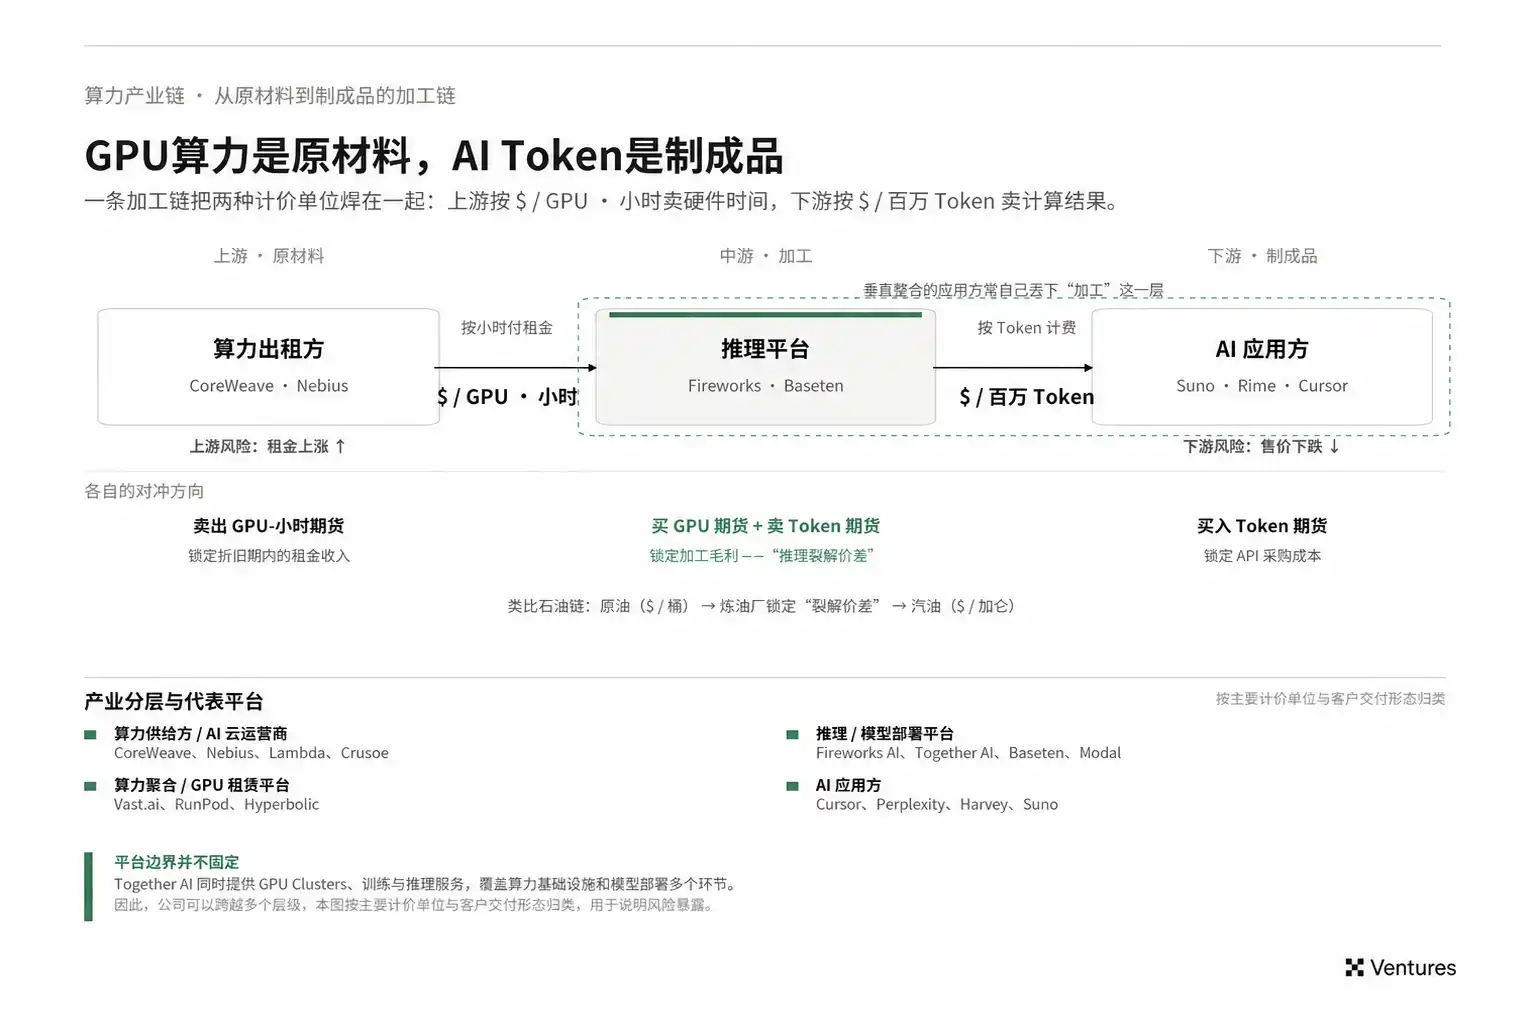
However, GPU-hour and AI Token are currently at very different levels of standardization.
Although GPUs also have differences in models, regions, interconnection methods, cluster sizes, and SLAs, it is possible to gradually define standard specifications around a particular generation of chips, delivery deadlines, and regions. An H100 or H200 still has relatively clear boundaries in terms of technical attributes.
On the other hand, Tokens lack a stable economic unit. Settlement based solely on the quantity of Tokens makes it difficult to include different models and service qualities in the same financial contract. The same one million Tokens could come from models with completely different capabilities and could correspond to completely different latencies, throughputs, and stabilities. Actual procurement prices for enterprise clients are often lower than publicly quoted API prices, making the listed price itself difficult to be directly used as a financial settlement benchmark.
Additionally, technological deflation further exacerbates the difficulty of pricing AI Tokens. As model architectures, inference frameworks, and hardware efficiency continue to improve, the computing costs for tasks of equal quality may significantly decrease in a short period of time. As the term extends, the market not only needs to predict the supply and demand of Tokens but also how many Tokens and GPUs will be needed for one unit of "intelligence" in the future.
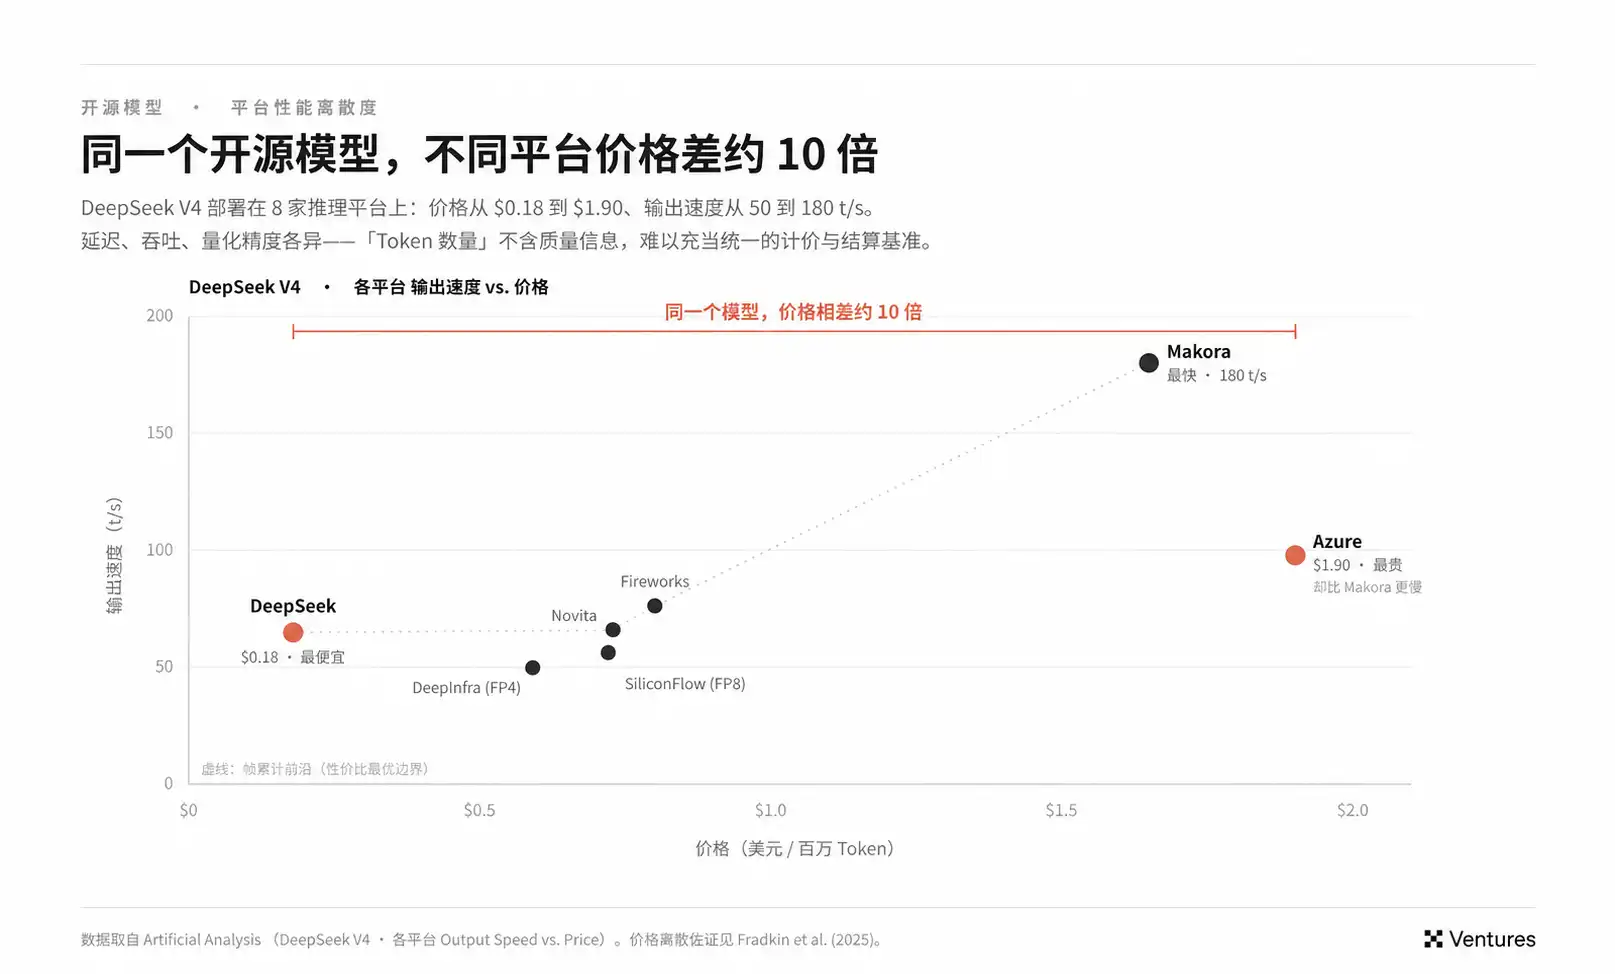
Therefore, standardization on the demand side may not necessarily start directly from Token futures. What is more likely to emerge first is a model basket, Router, and workload pricing: defining a coding, search, or other task as a relatively stable service unit, and then having the underlying system dynamically select models and providers. Only when such workloads have enough real transactions, will the market be ready to further develop indices and derivatives.
GPU-hour is closer to a basic commodity, while workload is closer to final economic demand. The standardization process between the two will determine the ultimate underlying asset of the computing power financial market.
Welcome to join the official BlockBeats community:
Telegram Subscription Group: https://t.me/theblockbeats
Telegram Discussion Group: https://t.me/BlockBeats_App
Official Twitter Account: https://twitter.com/BlockBeatsAsia

 Related Articles