IOSG: ZKVM’s way of survival, detailing the factional dispute between zkVM and zkEVM
Original title: 《 IOSG Weekly Brief |ZKVM's Way of Survival, a detailed explanation of the factional struggle 》
Original author: Bryan, IOSG Ventures
In the past 2022, the main focus of discussion on rollup seems to be on ZkEVM, but don't forget that ZkVM is also another means of expansion. Although ZkEVM is not the focus of this article, it is worth recalling the differences between ZkVM and ZkEVM in several dimensions:
Compatibility: Although both are expansion, the focus is different. ZkEVM focuses on directly achieving compatibility with the existing EVM, while ZkVM is positioned to achieve complete expansion, that is, to optimize the logic and performance of dapp, and compatibility is not the primary priority. Once the underlying layer is built, EVM compatibility can also be achieved.
Performance: Both have relatively foreseeable performance bottlenecks. The main bottleneck of ZkEVM is the extra cost generated when it is compatible with EVM, which is not suitable for encapsulation in the ZK proof system. The bottleneck of ZkVM is that the introduction of instruction set ISA makes the constraints of the final output more complex.
Developer experience: Type II ZkEVM (such as Scroll, Taiko) focuses on compatibility with EVM Bytecode. In other words, EVM code at the Bytecode level and above can generate corresponding zero-knowledge proofs through ZkEVM. For ZkVM, there are two directions. One direction is to make its own DSL (such as Cairo), and the other is to target compatibility with existing more mature languages such as C++/Rust (such as Risc 0). In the future, we expect that native solidity Ethereum developers will be able to migrate to ZkEVM at no cost, and newer and more powerful applications will run on ZkVM.
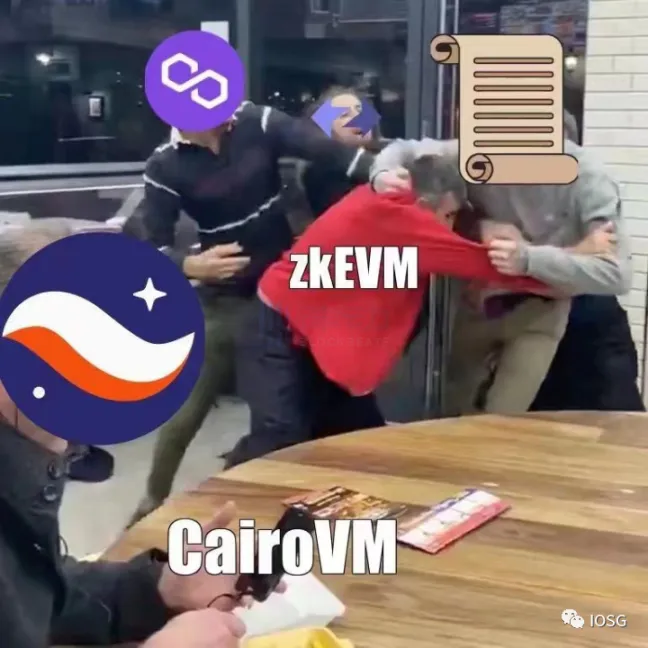
Many people should still remember this picture. The fundamental reason why CairoVM is not involved in the ZkEVM factional struggle is the difference in design ideas
Before discussing ZkVM, we first think about how to implement the ZK proof system in the blockchain. Generally speaking, there are two ways to implement circuits - circuit-based systems and virtual machine-based systems.
First, the function of a circuit-based system is to directly convert a program into constraints and feed them into a proving system; a virtual machine-based system executes a program through an instruction set (ISA), generating an execution trace in the process. This execution trace is then mapped into constraints and then fed into the proving system.
For a circuit-based system, the computation of the program is constrained by each machine that executes the program. For a virtual machine-based system, the ISA is embedded in a circuit generator and generates constraints for the program, while the circuit generator has limitations such as instruction set, operating cycle, memory, etc. The virtual machine provides universality, that is, any machine can run a program as long as the operating conditions of the program are within the above limitations.
In a virtual machine, a zkp program goes through the following process:

Image source: Bryan, IOSG Ventures
Pros and cons:
From a developer’s perspective, developing in a circuit-based system usually requires a deep understanding of the cost of each constraint. However, for writing virtual machine programs, circuits are static, and developers need to be more concerned about instructions.
From a verifier’s perspective, assuming that the same pure SNARK is used as the backend, circuit-based systems and virtual machines differ greatly in the versatility of circuits. Circuit systems produce different circuits for each program, while virtual machines produce the same circuits for different programs. This means that in a rollup, the circuit system needs to deploy multiple verifier contracts on L1.
From the application point of view, the virtual machine makes the logic of the application more complex by embedding the memory model into the design, and the purpose of using the circuit system is to improve the performance of the program.
From the perspective of system complexity, the virtual machine incorporates more complexity into the system, such as the memory model, communication between the host and the guest, etc., while the circuit system is simpler in comparison.
Below is a preview of the different circuit-based and VM-based projects currently in L1/L2:

Image credit: Bryan, IOSG Ventures
Design principles for VMs
In VMs, there are two key design principles. First, make sure the program is executed correctly. In other words, the output (i.e., constraints) should match the input (i.e., program) correctly. This is usually done through the ISA instruction set. Second, make sure the compiler works correctly when converting from the high-level language to the appropriate constraint format.
1. ISA instruction set
Specifies how the circuit generator works. Its main responsibility is to correctly map instructions into constraints, which are then fed into the proving system. ZK systems all use RISC (Reduced Instruction Set). There are two ISA options:
The first is to build a custom ISA, which can be seen in the design of Cairo. Generally speaking, there are four types of constraint logic.
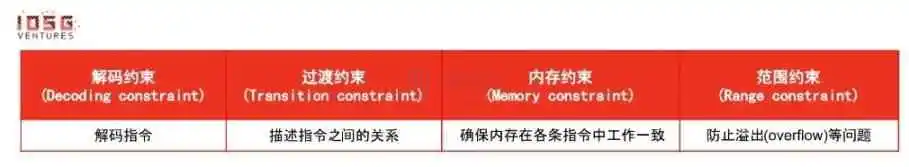
The basic design focus of a custom ISA is to ensure that there are as few constraints as possible so that both execution and verification of the program can run quickly.
The second is to use an existing ISA, which is adopted in the design of Risc 0. In addition to targeting clean execution time, existing ISAs such as Risc-V offer additional benefits such as being friendly to front-end languages and backend hardware. One (potential) question that remains to be answered is whether existing ISAs will fall behind in verification time (as verification time is not a primary design consideration for Risc-V.
2. Compiler
Generally speaking, a compiler is something that translates a programming language into machine code. In the context of ZK, this refers to compiling from a high-level language like C, C++, Rust, etc. into a low-level code representation of a constraint system (R1CS, QAP, AIR, etc.). There are two approaches,
Design a compiler based on existing zk circuit representations -- for example, in ZK, circuit representations start with directly callable libraries like Bellman and low-level languages like Circom. To aggregate different representations, compilers like Zokrates (which is also a DSL) aim to provide an abstraction layer that can compile to arbitrary lower-level representations.
Build on (existing) compiler infrastructure. The basic logic is to use an intermediate representation for multiple front-ends and back-ends.
Risc 0's compiler is based on multi-level intermediate representation (MLIR), which can generate multiple IRs (similar to LLVM). Different IRs give developers flexibility because different IRs have their own design focus. For example, some of the optimizations are specifically for hardware, so developers can choose according to their own wishes. Similar ideas can also be seen in vnTinyRAM and TinyRAM using GCC. ZkSync is another example of leveraging compiler infrastructure.
In addition, you can also see some compiler infrastructure for zk, such as CirC, which also borrows some design concepts from LLVM.
In addition to the two most critical design steps mentioned above, there are some other considerations:
1. The trade-off between the security of the system and the cost of verification
The higher the number of bits used by the system (that is, the higher the security), the higher the cost of verification. Security is reflected in the key generator (such as the elliptic curve in SNARK).
2. Compatibility with front-ends and back-ends
Compatibility depends on the validity of the intermediate representation for the circuit. The IR needs to strike a balance between correctness (whether the output of the program matches the input + whether the output conforms to the proof system) and flexibility (supporting multiple front-ends and back-ends). If the IR was originally designed to solve a low-degree constraint system like R1CS, compatibility with other higher-degree constraint systems such as AIR will be difficult.
3. Hand-crafted circuits are required for efficiency
The disadvantage of using a general purpose model is that it is less efficient for some simple operations that do not require complex instructions.
Briefly describe some previous theories,
Before Pinocchio protocol: Verifiable computing was achieved, but the verification time was very slow
Pinocchio protocol: It provides theoretical feasibility in terms of verifiability and verification success rate (that is, the verification time is shorter than the execution time of the program), and is a circuit-based system
TinyRAM protocol: Compared with Pinocchio protocol, TinyRAM is more like a virtual machine, introducing ISA, thus getting rid of some restrictions, such as memory access (RAM), control flow, etc.
vnTinyRAM protocol: It makes key generation not depend on each program, providing additional versatility. Expand the circuit generator, that is, it can handle larger programs.
All of the above models use SNARK as their backend proof system, but especially when dealing with virtual machines, STARK and Plonk seem to be a more suitable backend, fundamentally because their constraint systems are more suitable for implementing CPU-like logic.
Next, this article will introduce three STARK-based virtual machines - Risc 0, MidenVM, CairoVM. In short, in addition to using STARK as a proof system, they each have some differences:
Risc 0 uses Risc-V to achieve the simplicity of the instruction set. R 0 is compiled in MLIR, a variant of LLVM-IR designed to support a variety of existing general-purpose programming languages, such as Rust and C++. Risc-V also has some additional benefits, such as being more hardware-friendly.
Miden aims to be compatible with the Ethereum Virtual Machine (EVM) and is essentially a rollup of the EVM. Miden has its own programming language now, but is also working on supporting Move in the future.
Cairo VM is developed by Starkware. The STARK proof system used by these three systems was invented by Eli Ben-Sasson, currently the President of Starkware.
Let's take a closer look at the differences:

* How to read the table above? Some notes...
Word size - Since the constraint system these VMs are based on is AIR, which functions similarly to CPU architectures, it is appropriate to choose the CPU word size (32/64 bits).
Memory access - Risc0 uses registers mainly because the Risc-V instruction set is register-based. Miden mainly uses the stack to store data because AIR functions similarly to a stack. CairoVM does not use general-purpose registers because the cost of accessing main memory is low in the Cairo model.
Program feed - There are trade-offs between different methods. For example, for the mast root method, it needs to decode when processing instructions, so the cost of the prover is higher in programs with more execution steps.
Bootloading methods try to balance the prover cost and the verifier cost while maintaining privacy.
Non-determinism - Non-determinism is an important property of NP-complete problems. Exploiting non-determinism helps to quickly verify past executions. On the other hand, it adds more constraints, so there will be some compromises in verification.
Acceleration on complex operations - Some calculations are slow on the CPU. For example, bit operations like XOR and AND, hash programs like ECDSA, and range-checks... Most of them are operations that are native to blockchain/crypto but not native to the CPU (except bit operations).
Implementing these operations directly through the DSL can easily lead to the exhaustion of the proof cycle.
Permutation/multiset (permutation/multi-column combination) - heavily used in most zkVMs, with two purposes -- 1. Reduce the cost of the verifier by reducing the storage of the full execution trace 2. Prove that the verifier knows the full execution trace
Finally, I would like to talk about the current development of Risc 0 and why it excites me.
Current development of R 0:
a. The compiler infrastructure of the self-developed "Zirgen" is under development. It will be interesting to compare the performance of Zirgen with some existing zk-specific compilers.
b. Some very interesting innovations, such as field extension, can achieve more solid security parameters and operate on larger integers.
c. Witnessing the challenges seen in the integration between ZK hardware and ZK software companies, Risc 0 uses a hardware abstraction layer to allow for better development on the hardware side.
d.Still a work-in-progress!
Support for hand-crafted circuits, supporting multiple hashing algorithms. Currently, dedicated SHA 256 circuits have been implemented, however, not all needs are met. I believe the choice of which type of circuit to optimize depends on the use case provided by Risc 0. SHA 256 is a very good starting point. On the other hand, the positioning of ZKVM gives people flexibility, for example, they don’t have to worry about Keccak if they don’t want to :)
Recursion: This is a big topic, and I prefer not to delve into it in this report. It is important to know that as Risc 0 tends to support more complex use cases/programs, recursion is more urgently needed. To further support recursion, they are currently working on a hardware-side GPU acceleration solution.
Handling non-determinism: This is a property that ZKVM must deal with, while traditional virtual machines do not have this problem. Non-determinism can help virtual machines execute faster. MLIR is relatively good at dealing with problems in traditional virtual machines, and it is worth looking forward to how Risc 0 embeds non-determinism into the ZKVM system design.
WHAT EXCITES ME:
a. Simple and verifiable!
In distributed systems, PoW requires a high level of redundancy because people don't trust each other and need to repeatedly perform the same calculations to reach consensus. By leveraging zero-knowledge proofs, the implementation of states should be as easy as agreeing that 1+1=2.
b. More practical use cases:
In addition to the most direct expansion, more interesting use cases will become feasible, such as zero-knowledge machine learning, data analysis, etc. Compared with specific ZK languages such as Cairo, Rust/C++ is more universal and powerful, and more web2 use cases run on Risc0 VM.
c. More inclusive/mature developer community:
Developers interested in STARK and blockchain no longer have to relearn DSL, just use Rust/C++.
Original link
Welcome to join the official BlockBeats community:
Telegram Subscription Group: https://t.me/theblockbeats
Telegram Discussion Group: https://t.me/BlockBeats_App
Official Twitter Account: https://twitter.com/BlockBeatsAsia

 Related Articles